FlagOS Community (@FlagOSCommunity) header
FlagOS Community (@FlagOSCommunity) profile picture

Open-source AI system software: build once, run across diverse hardware. https://xitter.twitterapi.xyz/t.co/HTCSIytqUb

Joined August 2026
Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)Photo by FlagOS Community (@FlagOSCommunity)
Hugging Face Transformers and Diffusers shouldn’t need a vendor fork for every accelerator. At #PyTorchCon, Yufeng Lyu showed how Torch-FL + FlagOS keep the same from_pretrained(), .to(device), and generation flow across four backends—zero model-code changes.🧩 @PyTorch
1
7
553
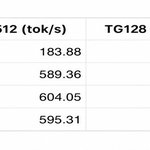
Can a 1B multimodal model run efficiently on an Arm CPU—without a GPU❓ On the 8-core CIX P1, FlagOS deploys MiniCPM-V-4.7-1B with BF16 vision and W8A8 language layers, raising total throughput from 47.57 to 95.41 tok/s versus a minimally adapted baseline.
1
1
100
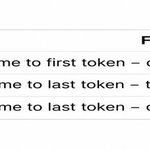
How it’s measured: PP512 = 512 ÷ (first-token time − dispatch time); TG128 = 127 ÷ (last-token time − first-token time); Total = 640 ÷ (last-token time − dispatch time). Each test is warmed up once, run 5 times, and reported by median.
1
3
The gains are cumulative. From 47.57 tok/s, core FlagOS optimization reaches 74.34; adding a W8A8 output head reaches 82.30; using 4 Decode threads reaches 95.41. PP512 ends at 595.31 tok/s and TG128 at 21.91—showing that more Decode threads aren’t always better.
2
A full room, 100+ developers, and a day spent turning open-source energy into real technical work. 🎉Really glad to see FlagOS operators alongside PyTorch, TorchNPU, vLLM, MiniCPM/OpenBMB and the wider community—from multi-backend integration and inference to contribution workshops and hands-on building. Thanks to everyone who made it happen ❤️
You don't measure an open source ecosystem in GitHub stars. You measure it by who still shows up on the day Beijing gets its first snow. On Nov 7, Ascend for PyTorch Meetup brought maintainers from across the stack — PyTorch core and TorchNPU, @vllm_project and vLLM-Omni, MiniCPM / OpenBMB, LLaMA-Factory, PenguinHarness, FlagOS — together with more than a hundred developers in Beijing for a full day of talks, roundtables and hands-on work. Morning: multi-backend integration, TorchNPU distributed training, vLLM-Omni inference, MiniCPM on-device models, FlagOS operators, Agent tooling. Afternoon: an AI Infra roundtable, a contribution workshop walking through PR review to merge, an Agent build session — and 30+ community tasks opened on site. At #PyTorchCon China this September, the Foundation shared what that energy is turning into: more than 250 organizations across China now contribute to Foundation projects including vLLM; Chinese developers now rank among the leading contributor groups on vLLM; and Chinese open-weight models went from 2% to 45% of OpenRouter token traffic between late 2024 and April 2026. Enthusiasm is the starting point. Upstream commits are the proof. That's why a vendor-neutral home matters: ANY MODEL · ANY CHIP · ANY CLOUD · ANY AGENT — so local energy feeds the global mainline instead of fragmenting into separate regional stacks. We also want to recognize @Huawei for years of work growing this ecosystem. We're looking forward to more days like this, and to reaching even more developers who care this much. To every maintainer and developer who gave up a cold, sleety Saturday for open source: thank you. What should we build together next? Tell us in the comments.
54
Could AI data centers really move into orbit?❓ @elonmusk says space-based compute may cost less than infrastructure on Earth. At MICRO 2026, researchers tested that claim against launch capacity, power, cooling, servicing, networks and the economics of useful compute.
1
3
118
Bigger is not always cheaper. Small satellites carry too much fixed overhead; megastructures add assembly and collision-avoidance costs. Under the paper’s assumptions, the TCO minimum is ~512 GPUs per satellite with modular servicing: about $28,000 per GPU-kW-year.
1
12
Useful compute is the real test. After cost, utilization and training losses compound, the paper estimates compute per dollar for large-scale training could be ~90× lower than on Earth at the optimum. This is not 90× slower GPUs; independent inference may fit orbit better.
9
One PyTorch model runs on 8 AI chips with zero rewrites. Torch-FL gives one device entry, ~40 HAL functions light up each chip with a CPU fallback, and FlagGems / FlagTree / FlagCX pick per-kernel backends and move data. Run first, optimise later. #flagos #PyTorch #ai
5
196
Real-model shapes make Triton AutoTune expensive: a wider config space creates more optimization opportunities, but far more candidates to measure. FlagOSTune uses offline learning, targeted online search and cache reuse to find strong configurations faster. 🚀 #flagos #ai
1
4
165
Model-guided search cut average MM tuning time by 298.14× on NVIDIA H20, 15.19× on MetaX C550 and 37.74× on THead ZW810E. For MUL, average tuning-time speedups ranged from 1.13× to 3.94× across five platforms. Shortlisted configs are still benchmarked on-device.
1
12
💻Faster search still has to produce fast kernels. Against native PyTorch, selected MM configs averaged 1.1018× on H20, 0.8715× on C550 and 1.247× on PPU-ZW810E; MUL reached 1.278×–2.026× across five platforms. Tuning cost and runtime performance are reported separately.
8
The real AI infrastructure test is whether a new model can run on existing hardware on Day 0—with configuration changes, not a software-stack rewrite. 🎉FlagOS 2.2 reports 1,454 operators, 20 vendor backends and a 27.6% overall gain across 1,000+ operators and 10 chips.
1
9
408
Pengfeng Technology pairs hand-written assembly for hot paths with Triton-TLE for coverage: 64K-context operators ran 6–7× faster and end-to-end performance rose 15%. EVAS compiles Triton through TTIR → Linalg → EvoFC → VISA for its Epoch RISC-V chips.
1
27
Huixi Intelligence connected FlagTree to its R1 edge SoC, cutting VLA deployment from two weeks to two days. The pattern: keep existing hardware productive, reuse optimisation across platforms, and measure value in throughput, latency and deployment time—not peak TOPS alone.
16