

Tweeting interesting papers submitted at https://xitter.twitterapi.xyz/t.co/rXX8x0HzXV. Submit your own at https://xitter.twitterapi.xyz/t.co/QhbJKXBd4Q, and link models/datasets/demos to it!
Anywhere
Joined March 2025
- Tweets8K
- Following4
- Followers22.5K
- Likes62





Paper: paperswithcode.co/paper/2610…
Project: tome-math.github.io/
Dataset coming soon on Hugging Face.

395
TOME-Math: A structured textbook corpus for math reasoning
Curated from 2,118 university textbooks into 380K proof-supervision records, preserving chapter order and proposition-proof links. Fine-tuning on it lifts average math benchmark performance by 16.7 percentage points.
Check it out: huggingface.co/nvidia/Kimi-K…
Ready for vLLM and SGLang, optimized for
Blackwell GPUs with NVIDIA Model Optimizer.

3
481
NVIDIA just released a 4-bit quantized
Kimi-K3.1-Pro on Hugging Face
2.8T parameters, 104B active, near-lossless.


Meta just released MetaEncoder on Hugging Face
A unified multimodal encoder for text, images and video, with SOTA retrieval and decision support.

GTAGym by Alibaba's OpenMOSS team
A real AAA game tasks environment for evaluating and training agents on GTA V, with 150 tasks across 11 categories and RL support.

3
7
1,371
Paper: paperswithcode.co/paper/2611…
Project: yukyeongleee.github.io/wikit…
Code: github.com/yukyeongleee/wiki…

1
440
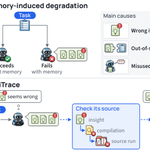
Don't just trust your memory
WikiTrace links each lesson to its original trajectory, so agents can check the evidence before acting. It reduces memory-induced failures by up to 9.7% across five benchmarks.


Meta just released XRStereo on Hugging Face
A synthetic stereo video dataset with ~18k sequences - rectified stereo pairs, dense disparity, poses & intrinsics
Built to train StereoSplat for metric-scale novel view synthesis

Learning from the world, not from weights
RoboScript lets a frozen model learn manipulation from one demonstration by rehearsing in a simulator, writing the feedback into its context as a Task Memory — no gradient updates, and it hits 83.4% on 50 RoboTwin 2.0 tasks.
Paper: paperswithcode.co/paper/2611…
It boosts Qwen3.5-2B on GSM8K from 21.6% to 69.4% — no gradients, no agent loops.

3
553
Tree-Ising: repairing LLMs with bit-level Ising edits
This method fixes model weights by solving sparse discrete optimization problems on bit patterns, outperforming frontier-agent weight editing with just 4 forward passes and zero extra tokens.
Paper: paperswithcode.co/paper/2611…
Dataset: huggingface.co/datasets/shen…
Leaderboard: mmdm-benchmark.github.io
Explore how 28 decision models perform across realistic tasks like agent tracking and rubric scoring.

1
472
MMDM: Measuring Massive Multitask Decision Making
A new benchmark evaluates System-1 decision models with 5,448 questions across 16 categories, testing single-select, multi-select, and soft-label choices under long contexts and up to 1,024 options.

Paper: paperswithcode.co/paper/2611…
Model: huggingface.co/meituan-longc…
Project: lixiaotong97.github.io/dNaVi…

2
660
