
CEO @EverMind https://xitter.twitterapi.xyz/t.co/s0pvFmiABl
Joined December 2025
- Tweets69
- Following64
- Followers780
- Likes246





Every AI product will need memory. Here's EverOS.
Next release (internal): LoCoMo 94.74% · AMA 80.89% · BEAM-1M 69.42% · SWE-ContextBench 34.34%
Current release: LongMemEval 94.00%
Built around two ideas:
Self-evolving. Every task becomes experience, experience becomes skills, and skills keep improving with use. Your agent gets better without retraining a model or rewriting a prompt.
Universal. One memory layer for any agent, any model, any app. Each agent gets exactly the context its task needs, in open source or in the cloud, on the same API.
Full write-up 👇
This quoted post is unavailable.
2
6
240
EverOS Cloud treats persistent memory as a first-class infrastructure layer — agents finally compound across sessions instead of starting from scratch. This is the missing primitive for long-term agents that genuinely improve with use.
xitter.twitterapi.xyz/evermind/status/211218…

Meet EverOS Cloud. 💛
Your agent shouldn’t have to start from scratch every time a conversation ends.
The preferences a user shared. The decisions made during a project. The approach that worked on a previous task. That context should be available when it matters again.
EverOS Cloud gives your agents persistent memory through an API:
• Remember users and retrieve relevant context across sessions
• Turn task experience into Cases and reusable Skill memories
• Bring conversations, images, and documents into your memory workflow
You build the agent experience. We handle the memory infrastructure, so you can spend less time maintaining the stack and more time making your product useful.
Subscribe to EverOS Cloud Pro and get 3× the standard Pro usage allowance for 6 months.
Start here:
everos.evermind.ai
1
9
335
Raven is the #1 paper of the month on @huggingface for September 🐦⬛
Thank you all. The Harness of Harnesses, built for RSI, and fully open source 👇

2
4
233

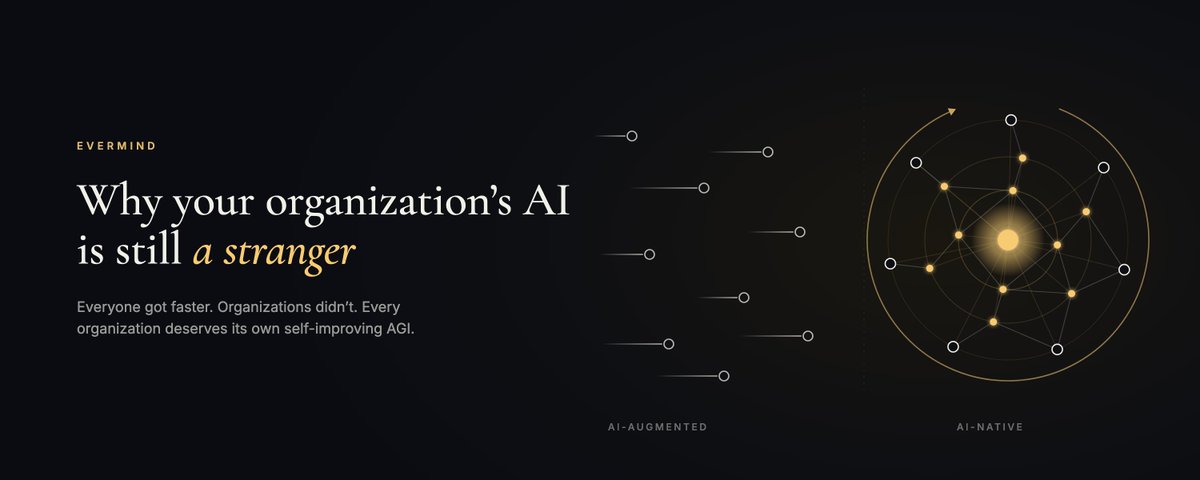
Everyone got faster with AI. Organizations didn't.
Because adding AI to an old org chart just makes each person faster. The way work moves, waits and gets aligned stays the same.
That's AI-augmented, not AI-native.
An AI-native org works differently:
Every piece of work points to one goal.
Humans and AI work side by side, and AI drives by default.
The system gets better on its own.
A model that knows nothing about your organization is a brilliant stranger.
Every organization deserves its own self-improving AGI.
2
2
124
Raven-built multi-agent forecasting systems took #1 and #2 on the FutureX weekly leaderboard 🐦⬛
Forecasting the future is one of the most valuable things intelligence can do. Human experts do it by pulling many sources, cross-checking facts, weighing evidence, and only then making a call.
We built that workflow on Raven, with Raven-Research at the core:
• Gather: agents search the web for each question
• Analyze: they cross-verify sources and draft a forecast
• Verify: a verifier agent approves it before submission
FutureX-Online, Sep Week 4:
🥇 Onyx, 53.06: all sub-agents run on GPT-5.6-Sol
🥈 Basalt, 52.73: DeepSeek V4-Pro, DeepSeek Flash, GPT-5.6-Sol and Claude Fable 5.1 working together
One framework, two directions: many agents on a single model, or many models in one team. That's the Harness of Harnesses in practice.

🛠️ Code: github.com/EverMind-AI/Raven
🌐 Try Raven: raven.evermind.ai
Onyx (Nevar-B) and Basalt (Nevar-A) are our Raven-based submissions.
📊 Leaderboard: futurex.live

1
2
247
Raven just hit #1 Paper of the Day on @huggingface 🎉
Technical report: huggingface.co/papers/2609.3…
Raven's two core ideas:
• The Harness of Harnesses: compose specialized agents into one team
• Built for RSI: the harness itself can be rewritten and improved by AI
Fully open source. Come build with us 👇
github.com/EverMind-AI/Raven


The response to Raven these past two days has blown us away. Thank you! 🐦⬛
Clearly the ideas resonate:
• One harness can't be best at everything, so Raven turns its own specialist harnesses and the agents you already use (Claude Code, Codex and more) into one team
• RSI goes beyond skills: the whole harness, orchestration layer included, is built to be rewritten and improved by AI
And it's not just an idea. It's backed by research. Our technical report is out:
Raven: The Harness of Harnesses for Composable Agentic Intelligence
📄 arxiv.org/abs/2609.33439
🤗 huggingface.co/papers/2609.3…
An upvote on Hugging Face means a lot 🙏

The response to Raven these past two days has blown us away. Thank you! 🐦⬛
Clearly the ideas resonate:
• One harness can't be best at everything, so Raven turns its own specialist harnesses and the agents you already use (Claude Code, Codex and more) into one team
• RSI goes beyond skills: the whole harness, orchestration layer included, is built to be rewritten and improved by AI
And it's not just an idea. It's backed by research. Our technical report is out:
Raven: The Harness of Harnesses for Composable Agentic Intelligence
📄 arxiv.org/abs/2609.33439
🤗 huggingface.co/papers/2609.3…
An upvote on Hugging Face means a lot 🙏
Raven 0.2.0 — The Harness of Harnesses, built for RSI. 🐦⬛
One harness can't be best at everything. Raven combines its own specialist harnesses (Research, Code, Design, Oncall) with the agents you already use (Claude Code, Codex and more) into one team.
And it's built for RSI, and not just at the skill level. The whole harness can be rewritten by AI: prompts, policies, strategy code, playbooks. Every sub-harness, including the orchestration layer itself, is its own instance that can be improved.
With Raven you can:
1. Orchestrate many agents as one team. Raven's sub-harnesses and external agents work in one task graph with shared memory across sub-agents, powered by leading orchestration (0.963 Node F1 on the Multi-Agent Orchestration Benchmark).
2. Run long, complex tasks. Oncall and proactive execution keep work going for days, from scientific research loops to shipping a full Godot game.
3. Build vertical agents with RSI. Use Raven's RSI to develop and refine an agent for your domain, and we'll optimize it with you. Experimental for now; reach out to the Raven team(Discord:discord.gg/VVSm8MESch).
More in the video and slides below. Open source, Apache-2.0.
github.com/EverMind-AI/Raven (lots of work made with Raven lives there, and much of this launch's material was made with Raven too)
Raven 0.2.0 — The Harness of Harnesses, built for RSI. 🐦⬛
One harness can't be best at everything. Raven combines its own specialist harnesses (Research, Code, Design, Oncall) with the agents you already use (Claude Code, Codex and more) into one team.
And it's built for RSI, and not just at the skill level. The whole harness can be rewritten by AI: prompts, policies, strategy code, playbooks. Every sub-harness, including the orchestration layer itself, is its own instance that can be improved.
With Raven you can:
1. Orchestrate many agents as one team. Raven's sub-harnesses and external agents work in one task graph with shared memory across sub-agents, powered by leading orchestration (0.963 Node F1 on the Multi-Agent Orchestration Benchmark).
2. Run long, complex tasks. Oncall and proactive execution keep work going for days, from scientific research loops to shipping a full Godot game.
3. Build vertical agents with RSI. Use Raven's RSI to develop and refine an agent for your domain, and we'll optimize it with you. Experimental for now; reach out to the Raven team(Discord:discord.gg/VVSm8MESch).
More in the video and slides below. Open source, Apache-2.0.
github.com/EverMind-AI/Raven (lots of work made with Raven lives there, and much of this launch's material was made with Raven too)

The more you use it, the smarter it gets — it evolves on its own.
Today we're launching everme — personal memory for the age of agents.
The idea: you'll use many different agents, but your memory should belong to you.
Just give your agent one sentence, and everme manages your memory across all of them — with self-evolving skills, zero maintenance, and a 2-minute cold start.
With everme:
• Claude Code and Codex share memory
• openclaw and hermes agent share memory
• memory travels across platforms and machines
→ everme.evermind.ai
Today we're launching everme — personal memory for the age of agents.
The idea: you'll use many different agents, but your memory should belong to you.
Just give your agent one sentence, and everme manages your memory across all of them — with self-evolving skills, zero maintenance, and a 2-minute cold start.
With everme:
• Claude Code and Codex share memory
• openclaw and hermes agent share memory
• memory travels across platforms and machines
→ everme.evermind.ai
To evaluate your Claw agent's evolutionary capabilities, you can utilize EvoAgentBench, the second benchmark dedicated to agent evaluation on Hugging Face.

5
645
EverMind is Hiring: Technical PM (Agent OS & Memory)
Based in Silicon Valley | Shanghai | Beijing
What we need:
Tech + Product: Deeply understand Agent execution mechanics under the hood (OpenClaw/Hermes Agent is a +).
AI-Native: Fluent in Vibe Coding. You can spin up working demos yourself to validate concepts.
LTM Focus: Intensely driven to build an Agent OS with true Long-Term Memory.
Flexible setup: Open to part-time/intern as a trial.
DM me to chat!
AI self-evolution is undoubtedly the ultimate core of next-gen AI—and true evolution is fundamentally built on Long-Term Memory. 🧠
At EverMind, we believe every AI of the future must have long-term memory. If you want to build an AI that continuously adapts and unlocks a massive data flywheel, you need EverOS. ♾️
The update we’ve been polishing for ages is FINALLY live! 🚀 It's way more than just a product update—Methods, Benchmarks, Usecases, and a fresh site are all here.
Here’s the breakdown: 👇
1️⃣ EverMemOS ➡️ EverOS: The ultimate one-stop shop. EverOS now empowers your Agents with self-evolution capabilities—just like Hermes Agent. Plus, we’ve added full multi-modal support. Use our Methods to customize Usecases into your own Agents, then benchmark to optimize them. It's the absolute all-in-one king. 👑
2️⃣ EvoAgentBench is LIVE & Open-Source: The perfect tool to test your custom Claude Code, OpenClaw, Hermes, or any Agent you throw at it. 📊
3️⃣ Brand New Website: Aesthetics matter. The new vibe, colors, and interactive experiences are absolutely off the charts. 🎨🔥
Dive in here:
github.com/EverMind-AI/EverO…
#EverOS #AI #AgentTools #Harness @Memory #OpenClaw #Hermes #ClaudeCode

1
482
Every major wave of computing has been defined by how we store and retrieve information.
Mainframes, databases, the cloud. AI is no different. The teams that competed at Memory Genesis 2026 understand something most of the industry has not fully internalized yet: memory is not just infrastructure. It is intelligence itself.
This event was a glimpse of that future. Grateful to everyone who showed up to build it with us.

The Memory Genesis Competition 2026 Final Event kicked off today in Mountain View, CA.
Hosted by @shanda_group and @evermind, and supported by OpenAI and AWS, the Memory Genesis Competition 2026 brought together innovators, researchers, investors, and builders to explore how next-generation memory technologies will define the future of AI.
A landmark day for the memory industry. Here is what went down. (Stay until the end. You will want to see how this room looked.)
🧵

2
493
MSA这么基础的工作,还得到了大家这么高的关注。
GitHub 链接(欢迎继续点星⭐️):github.com/EverMind-AI/MSA
论文链接:zenodo.org/records/19103670


1
6
324
MSA (Memory Sparse Attention) represents our significant exploration in the field of long-term memory. It stands as the first end-to-end long-term memory framework for large models to genuinely achieve a 100M context length. Interestingly, as the memory length scales from 16K to 100M, the model's performance score decreases by a mere 9%, demonstrating highly robust scalability.
Main contribution:
1,We propose MSA, an end-to-end trainable, scalable sparse attention architecture with a
document-wise RoPE that extends intrinsic LLM memory while preserving representational
alignment. It achieves near-linear inference cost and exhibits < 9% degradation even when
scaling from 16K to 100M tokens.
2,We introduce KV cache compression to reduce memory footprint and latency while maintaining retrieval fidelity at scale. Paired with Memory Parallel, it enables high-throughput
processing for 100M tokens under practical deployment constraints, such as a single 2×A800
GPU node.
3,We present Memory Interleave, an adaptive mechanism that facilitates complex multi-hop
reasoning. By iteratively synchronizing and integrating KV cache across scattered context
segments, MSA preserves cross-document dependencies and enables robust long-range
evidence integration.
4,Comprehensive evaluations on long-context QA and Needle-In-A-Haystack benchmarks
demonstrate that MSA significantly outperforms frontier LLMs, state-of-the-art RAG systems and leading memory agents.
Welcome to feedback:
github.com/EverMind-AI/MSA
zenodo.org/records/19103670
We are looking for passionate talents to join our team! If you are interested in our work and vision, please don't hesitate to send us an email at evermind@shanda.com.

arxiv.org/pdf/2602.01313
EverMemBench是我们针对多人协作场景构建的长期记忆评测Benchmark,悄悄上线几周,就有了几百次下载。
这个benchmark的主要特点是第一次支持了多人多群组真实场景(之前的LoCoMo等场景都非常简单),且提供了训练集和测试集,方便进行RL等实验,同时,提供了中间过程的GroundTruth,方便研究方法每一步的影响。特别是构建这个BenchMark的方法也很有启发性,可以用来构建模拟试验场生成数据。
欢迎做长期记忆的朋友评测,多提建议!

我们昨天在 arXiv 上发了一篇新论文,填补了一个一直没人做的空白:多人、多群组场景下的记忆测试。
简单科普一下为什么这件事重要
之前测 AI 记忆能力的 benchmark,基本都是"两个人聊天"的场景:
LoCoMo(2024):最早系统测试多轮对话记忆,但本质上就是两个人对话,上下文约 16K tokens,规模偏小
LongMemEval(2024,ICLR 2025):把规模推到了 115K–1.5M tokens,定义了五个核心记忆能力,但仍然是一对一对话
问题是,现实世界不是这样的。你同时在多个群聊里,跟不同的人聊不同的事,AI 能记住谁在哪个群说了什么吗?
这就是 EverMemBench 要回答的问题。
下图是我用 @claudeai 最新功能生成的,你还别说,挺好看。


1
298
随着模型能力的提升,智能系统的行为将主要取决于提供给LLM的context。其核心在于,如何基于已有的memory(上下文历史)构建合理的context送给LLM。所以,context/memory/harness成为与LLM能力独立的一极。如何更低成本、更高准确率提取,就成为Agent技术的关键。memory将成为agent的核心组件。

In 2024 the question was: which LLM do we use?
In 2025 the question is: how do we make agents actually work in production?
In 2026 the question will be: which context layer are we building on?
Here is why that shift is already underway:

2
223
Memory Genesis Competition 2026 is in last call — submissions close on March 15.
You're also welcome to join us on April 4 at the Computer History Museum for an in-person gathering and high-signal conversations with the EverMind core team and leaders across OpenAI, AWS, research institutes, open-source communities, and the investment world.
Guess who will you meet? Follow the competition website for the latest updates: evermind.ai/activities
#AIMemory #AgentMemory #EverMemOS #AgenticAI #Hackathon #Developers #AIInfra

2
147