

https://xitter.twitterapi.xyz/t.co/DWae4fwKnJ
Palo Alto, CA
Joined October 2025
- Tweets136
- Following0
- Followers9.6K
- Likes151




Pinned Tweet
Today we release Ripple-65B Preview, our 65B dense LLM we pretrained from scratch.
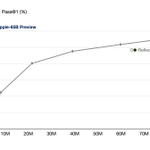
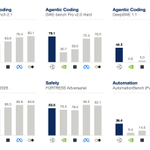
Ripple sets a new state-of-the-art for U.S. open-weight models in agentic coding tasks, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
Learn more: ricursive.com/ripple
Ripple-65B Preview is now available on ollama!
ollama.com/library/ripple-pr…


Ripple 65-B Preview from @RicursiveAI is on Ollama. Built for agentic coding, with up to 1M tokens of context. Run it locally with full zero data retention.
Last week we released Ripple-65B Preview. This Friday, come build with it.
Ricursive After Dark Hackathon: Fri Nov 13, 3PM–10PM, at our Palo Alto office. Compute, dinner, and hardware prizes.
Applications close Thursday, November 12 at noon PT. Accepted participants will be notified by email Thursday night with the address and full details.
luma.com/qnsar3a2?utm_source…

Apply here: jobs.ashbyhq.com/Ricursive%2…
Read about how we built Ripple-65B Preview: ricursive.com/ripple

4
222
Now live on Fireworks and Together as well! All inference endpoints available below:
Fireworks: fireworks.ai/models/firework…
Together: together.ai/models/ripple-65…
GMI Cloud: console.gmicloud.ai/model/ll…
OpenRouter: openrouter.ai/ricursiveai/ri…

Ricursive Intelligence retweeted

Very good and detailed review of our model from @Sam_Witteveen
Ripple 65B: A Chip Design Lab Just Beat Every US Open Model youtu.be/2dD4HXg-YJ4?is=BTHp…

Ricursive Intelligence retweeted
Update: the OpenRouter link is here: openrouter.ai/ricursiveai/ri…

Update: the OpenRouter link is here: openrouter.ai/ricursiveai/ri…
Thank you for your kind words!
Yes, our $32M R&D cost fully encompasses our pretraining ladder development, data mixing, evals, debugging, synthetic data generation, posttraining recipe development, and the final hero pre, mid, and posttraining run!

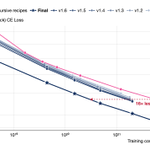
> we developed and trained Ripple-65B Preview for only $32M, which is one-tenth the cost of the previous open-weight SOTA on agentic coding¹
this is like the avengers of open model SOTA
¹ "Note that $32M is our full R&D cost starting from scratch, including pretraining ladder development, data mixing, evals, debugging, synthetic data generation, posttraining recipe development, and the final hero pretraining and posttraining run."

Thanks for a great partnership @nvidia!

Congrats to @RicursiveAI on Ripple-65B Preview, their first open model 🎉
It was trained on NVIDIA B300 GPUs & sharpened with open NVIDIA Nemotron post-training datasets.
Download the NVFP4 checkpoint from Hugging Face and run locally on DGX Spark 👉 huggingface.co/ricursiveAI/R…

26
3,196
Thank you for your genuine support @kimmonismus. We're just getting started!

Ok, *this is impressive*: Ricursive Intelligence just released Ripple-65B Preview, an open-weight AI model that it says outperforms much larger US models on a key agentic coding benchmark. And even runs locally on my DGX Spark.
Ripple scored 80.5% on Terminal-Bench 2.1, narrowly ahead of Reflection’s Beam-501B at 80.1%, according to the companies’ reported results!
The size comparison comes with a detail: Ripple uses all 65B parameters for each task, while Beam activates 23B of its 501B parameters.
Ricursive says Ripple was trained on 12 trillion tokens with a $32 million compute budget - from scratch. The model supports up to 1 million tokens of context and is available under Apache 2.0.

2
25
3,393
Proud to be a home to many Stanford alum and faculty, including our cofounders @Azaliamirh @annadgoldie!

@StanfordAILab faculty building incredible open models out in the wild!
Congratulations to the @RicursiveAI team!