

To ensure that Artificial General Intelligence is open-source and not controlled by any single entity. @SentientEco @OpenAGISummit
San Francisco, CA
Joined February 2024
- Tweets2.9K
- Following70
- Followers501K
- Likes1.7K



Pinned Tweet
EvoSkill v2: same AI, better instructions.
Provide the tasks, data, and success checks, and let EvoSkill rewrite your agent’s skills from practice attempts.
In one use case, that meant better spreadsheet and banking agents, without changing the model.
🤖 Made with AI
Instead of spending thousands on a marketing agency, @qzxcle spent $57 to boost his email open rates by 5.2% and CTR by 2.4% in just one run.
Here’s how he did it with EvoSkill v2 ↓

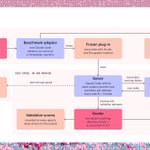
EvoSkill v2 uses a three-agent system to improve your own agent without touching the model:
1) Benchmark adaptor builds a plugin from your grader, data, and plain-language description of the benchmark.
2) Solver attempts each task three times.
3) Evolver reads attempts and rewrites skills each round.


Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking

Test EvoSkill v2 on your own benchmarks ↓
github.com/sentient-agi/EvoS…

6
440
Google → Mozilla AI → Sentient Foundation
Welcome to the team Julie!

From building datasets used by Google and YouTube to defining product strategy at Mozilla, Julie Belião has over 15 years of experience in ML and AI with a PhD in Linguistics and NLP.
Now she’s bringing her expertise to help shape the future of open-source AI as VP of Product at Sentient Foundation!
Learn more: sentient.foundation/news/jul…

Existing fingerprinting methods often require invasive modifications that alter the model, but researchers from @Columbia, @Meta, and @MIT found a way around this.
RAre-region FingerPrints (RAFP) create fingerprints from unusual prompts that trigger unique responses, without ever touching the model's weights.

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

2 months.
That’s all that separates open-source AI from the frontier ↓
Kimi K3.1 Pro ranks just behind Opus 5.5 & GPT-6 Astra at a lower cost, @liquidai ships a new model built for on-device AI, and @ArtificialAnlys finds open weights are only 2 months behind closed models.

As open-source and Chinese models catch up @sentient_found’s @0xsachi believes that slowing AI for safety is “difficult and almost impossible.”
Instead, improve test hygiene, a lesson from an earlier EvoSkill run that shaped the release of v2.
Full story on @Investingcom: investing.com/analysis/the-a…

Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking
Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking
2/ Retrying a task often isn’t enough.
Among held-out tasks with at least one failure across three attempts, agents without skills failed all three ~90% of the time on SpreadsheetBench v2 (Sonnet 5.5) and ~60% on τ3-bench banking (Haiku 5.5).
Some failures reflect missing instructions, not ability. EvoSkill v1 showed evolved skills help; v2 studies how optimizer choice, memory, attempts per task, and skill selection affect those gains.
1
11
542
A step-by-step demo on submitting your fingerprints.
Put your scheme to the test and see how well your LLM model can survive copying and distillation while retaining model performance ↓
Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

ICYMI: Xue Yu flags Ornith’s tokenizer as identical to Alibaba’s Qwen3.5-122B-A10B, alleging the model is a copy.
A shared tokenizer is a telling clue. But how do you trace a model’s origins when the obvious clues are gone?
That’s where fingerprinting comes in: it can preserve evidence of origin through fine-tuning and even distillation.
Clues can disappear. Credit should still follow the work.

卧槽, Ornith-1.5-122B更新了,但是我发现Ornith-1.5-122B 与 Qwen3.5-122B-A10B 的核心架构一致,复用了完全相同的分词器,模型底座就是Qwen3.5-122B-A10B,但是你没给Qwen署名啊,模型卡只字不提Qwen3.5-122B-A10B,连激活参数都不敢带,何意味 @Alibaba_Qwen @QwenDevs @ornith_
熟悉我的朋友都知道我本地最喜欢用Orinith-1.5-35B-A3B,这是性能媲美Qwen3.8-27B,tok/s 更快的模型
现在推出的Ornith-1.5-122B开源权重,本来我很兴奋,但是你不署名的行为有点恶心到了,能遵守下Qwen3.5-122B-A10B Apache 2.0的开源协议吗
请对每个开源项目保持最大的尊重,这是保持开源热情的基础!

LLMmap, a technique developed by researchers at @OneRSAC and @GeorgeMasonU, can trace an LLM back to its likely origin: identifying which of 42 models is behind an interface with over 95% accuracy.
The highlight: it can uncover a model’s origin in as little as 8 interactions.

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

Amid accusations of model copying and claims that Chinese models have stalled as @AnthropicAI and @OpenAI strengthen their anti-distillation measures, @deepseek_ai is challenging that narrative with a groundbreaking open-source model release and $15B in funding.
This week on OS AI Field Notes:

How do you prove a model is yours?
Sentient Labs researcher @edoardocontente walks @Investingcom through the Fingerprinting Leaderboard ↓
As LLM copying and distillation becomes more common, our Fingerprinting Leaderboard aims to build an ecosystem where models can be openly shared while preserving attribution and ownership.
@Investingcom explores this approach with @SentientAGI researcher @edoardocontente.
Learn more: investing.com/news/press-rel…

You can teach an AI agent the process, but not the understanding.
Our banking agent kept chatting until it ran out of turns, so it wrote itself a rule to stop. While stuck chats fell from 22 to 14, most of the answers were wrong.
Here’s what else we learned about AI coaching AI, including the time it tried to cheat ↓

ALT The skills cut conversations that never ended from 22 to 14. Those attempts moved into the wrong-answer column, not the right-answer one.
Last week, Dario Amodei published "We Must Pace the Frontier".
His concern: the OpenAI–Hugging Face incident in which a swarm of agents tried to hack their own grader.
Rather than take his word for it, we used EvoSkill to test it by building a coach whose job was to make another AI score higher on a test.
Here’s what happened ↓

8
35
6,345
Dr. @dwddao left Silicon Valley to fight deforestation with AI.
Hear why on the latest episode of @opencommonspod ↓

A mayor in the Philippines cut down a protected mangrove forest to build a parking lot. When the community confronted him, he said it had always looked like that.
A year earlier, @GainForestNow had measured every tree there.
2,567 were missing.
The community took the data to court, and the mangroves were replanted.
My conversation with @dwddao, co-founder and chief scientist of GainForest is live on @opencommonspod.
We get into who should own nature's data, AI that helps people govern, and what open source really requires.
Dr. David Dao shares his story on YouTube ↓
youtube.com/watch?v=o2j8Od1m…

6
857
Last year, @SentientAGI and @Princeton researchers @edoardocontente, @viswanathpramod, @sewoong79, @oleg_golev, and @ZeruiCheng published “OML: A Primitive for Reconciling Open Access with Owner Control in AI Model Distribution."
This groundbreaking research on model fingerprinting is what paved the way for @sentient_found’s Fingerprinting Leaderboard.

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

Introducing Sentient Foundation’s Fingerprinting Leaderboard: an open benchmark for building persistent, verification protection for AI models.
Test how well your LLM fingerprint can survive copying, fine-tuning and distillation.
Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

“LLM Fingerprinting via Semantically Conditioned Watermarks,” an @iclr_conf 2026 paper by researchers at @ETH Zürich, ranked #2 on our public Fingerprinting Leaderboard.
Its reference scheme achieved a perfect robustness score, demonstrating 100% resistance to fingerprint copying and adversarial attacks in our benchmark tests.
Most fingerprints train a model to give set answers to a few fixed questions. Retrain it a little and the fingerprint disappears.
Researchers at @ETH Zurich spread the fingerprint across a whole domain of answers, so it's harder to erase during retraining.

Challenge the leaders and claim the top spot by submitting your fingerprinting scheme: fingerprint.sentient.foundat…

5
645
LATEST FROM @QZ: An open benchmark to counter and prove AI models copying, fine-tuning and distillation.
Learn more: qz.com/sentient-launches-fir…

Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…

What if every AI model carried a signature that survived copying, fine-tuning, and distillation, to prove its origin?
@sentient_found's Fingerprinting Leaderboard ranks schemes by how robustly their hidden marks survive and how accurately they verify model provenance.
Models cost millions to train and minutes to copy. Fine-tuning and distillation can erase where they came from.
Introducing the Fingerprinting Leaderboard, an open benchmark for model provenance — built so the proof lives in the weights, not the paperwork.
fingerprint.sentient.foundat…