

Unified API for ANY AI model. Memory, RAG, Smart Routing, CLI, agents and MCP integrations out of the box.
Joined June 2025
- Tweets200
- Following30
- Followers155
- Likes765




we added 30 decision models to AnyAPI.ai this week:
baseten: elephant-1
baseten: joey-1
baseten: mammoth-1
cloudflare: clef
cloudflare: clef-flash
cloudflare: clef-omni
inception: mercury-decide
jaredpalmer: kev-4b
liquid: d1
liquid: d1-ultra
liquid: d1.1
microsoft: microsoft-decision-1
nace-ai: drex-max
nace-ai: drex-v1.5
nace-ai: drex-v2.0
openai: gpt-6-luna-decisions
perplexity: pplx-decider-flash-v1.2
perplexity: pplx-decider-v1.2
respan: span-01
respan: span-01-lite
respan: span-01-lite:free
respan: span-02
scaledown: classify-1
togethercomputer: tev1-4b-experimental
typesafe: jev-1.13
typesafe: jev-1.14
upstage: solar-decide
upstage: solar-decide-flash
typesafe: jev
convai: laya
🤖 Made with AI

1
6
287
AnyAPI.ai is now a native provider in @NousResearch hermes agent.
no core patches, no proxy wrapper. one plugin registers a provider profile and it shows up in the model picker next to the built-ins
hermes plugins install anyapi

3
9
285


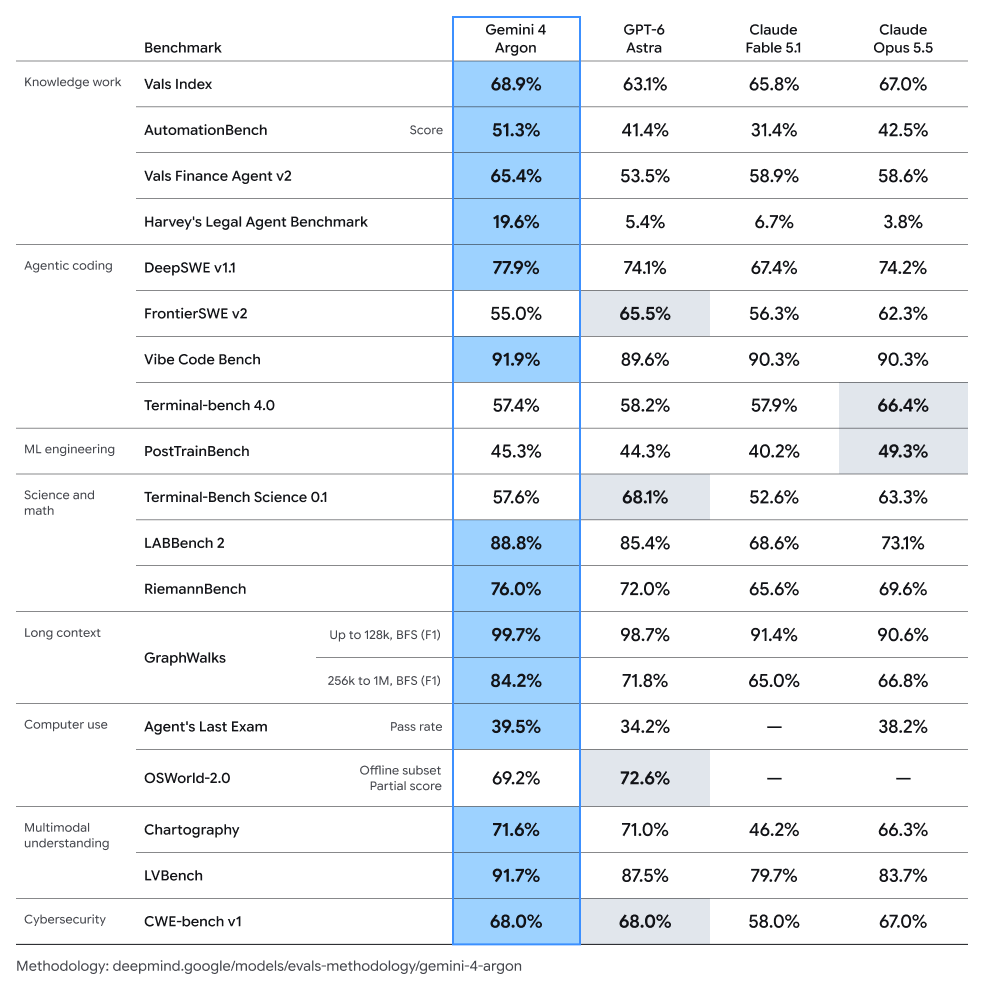
GPT-6 Sol beats Claude Opus 5.5 - 5x cheaper and the difference isn't even close
the test: infinite zoom into the Mandelbrot set as a single self-contained HTML file - WebGL shader, multi-precision math, seamless loop
cost : GPT-6 Sol: $0.07
Claude Opus 5.5: $0.35
what we saw:
• Opus burned 2.7x the tokens (17.6k vs 6.6k, most of it reasoning noise)
• Sol's zoom actually zooms: deep exponential dive into Seahorse Valley with plasma filaments, bloom, and a perfectly seamless 6-sec loop
• Opus 5.5 whole frame slowly rotates around a murky blob while the zoom crawls 6x slower - hypnotic in the worst way
• Sol's code: 2× more output per token, denser, runs smoother
verdict: Claude thinks longer. GPT delivers better.
2
9
642

Fable 5.1 charges 40× more than Gemini 3.8 Flash for the same task.
we threw both, plus GPT-5.6 Sol, at a working V12 engine and a
mechanical chronograph in three.js. same prompts, one shot, no retries.
the bill:
watch: Fable 5.1 $2.14 · Sol $0.08 · Gemini 3.8 Flash $0.05
engine: Fable 5.1 $1.30 · Sol $0.10 · Gemini $0.04
and here's the thing: fable's watch is genuinely the best one. the
escape wheel ticks in discrete steps. the hairspring breathes at 4Hz.
341 parts under a sapphire caseback. 24,346 tokens of pure gear-ratio
thinking went into it, and it shows.
Gemini nails museum framing in 75 seconds flat, then paints the whole
movement one shade of grey. Sol's take is clean and stylized, which
means the truth: it's a facade with hands.
plot twist: fable's 40× engine ships a real bug. idle RPM dips below
zero and the whole frame goes black. the watch is a masterpiece. the
engine, not so much.
so the real answer is ugly: 40× the price buys you the physics under
the dial. sometimes. which one are you picking?
1
7
285
GPT-5.6 SOL vs Claude Fable 5 vs Kimi k3 – 3d rubik's cube in @threejs
the setup: one prompt in, one html file out. streamed straight through AnyAPI, no agent loop, no tools, no filesystem, just a single standalone response per model
models: gpt 5.6 sol , claude fable 5 , kimi k3
prompt: a fully functional 3D Rubik’s Cube simulation in one HTML file, using Three.js via CDN, with automatic self-solving
results:
gpt 5.6 sol – 1.36s, 8,612 total tokens, $1.53, 825 lines
claude fable 5 – 1.26s, 10,725 total tokens, $3.16, 465 lines
kimi k3 – 302.99s, 36,565 total tokens, $3.27, 733 lines
observations:
• sol and fable both returned almost instantly; kimi took 303s on the same task
• fable shipped the shortest file at 465 lines, while sol shipped the largest valid file at 825
• kimi used 4.2x the total tokens of sol and still landed in roughly the same price band as fable
Grok 4.5 just one-shotted a full 3D Starship landing
One prompt. One HTML file. No cleanup. No extra setup.
We asked @grok to build a cinematic Starship touchdown at sunrise: landing burn, deployed legs, dust, steam, Boca Chica tower, ocean horizon — the whole shot.
And it actually shipped.
Stats:
3 min 1 sec
14,511 tokens
~$0.09
That’s the wild part: not just a cool demo — a legit 3D landing scene, one-shot, for nine cents.
People love arguing about which model is smartest. We’re starting to care a lot more about which one actually ships.
cc @spacexai
1
7
232
GPT-5.6 Sol vs Opus 5 vs Qwen 3.8 Max
we ran all three on two one-shot 3D hero-object prompts
1)Fabergé egg on a black background
2)vintage diving helmet on a black background
results:
GPT-5.6 Sol
generation time: ~143s avg
output: ~8 600 tokens avg
cost: ~$0.34
Claude Opus 5
generation time: ~214s avg
output: ~17 800 tokens avg
cost: ~$0.53
Qwen 3.8 Max
generation time: ~258s avg
output: ~17 400 tokens avg
cost: ~$0.14
the interesting part:
Sol was fastest and most consistent across both prompts
Opus 5 wrote the longest outputs — lots of detail, but slower(faster in terms of tps)
Qwen 3.8 Max was the cheapest by a wide margin, and when it worked, the code was competitive
simpler objects (diving helmet) rendered reliably for all three
more complex materials (Fabergé egg) separated the models
the takeaway: Sol is the practical all-rounder. Opus 5 is the detail-heavy option. Qwen 3.8 Max is the budget pick with strong potential.
which model won?
1
11
528

We just pushed a performance update to AnyAPI, and everything is now sub-second.
— AI streaming starts in under 1s
— Dashboard/catalog loads in ~0.5s
— API latency is down to ~150ms
One API, every major model, SOC 2 and ISO 27001 compliant. Built for production, without the latency.

4
137
Kimi K3 LIVE on AnyAPI
We gave Kimi K3 one prompt: build a 3D Duck Hunt remake in a single HTML file.
9,582 tokens | ~130s | $0.14
What it built:
- 3D pixel-art ducks launching from bushes
- Depth-layered sky and grass field
- Working crosshair with fall animations on hit
- The classic 8-bit dog popping up, laughing on misses
No assets. No dependencies. One file. One prompt.
Docs, guides below:
GPT-5.6 Sol vs Fable 5 vs Opus 4.8
Built a Boeing 777 GE90 turbofan engine cutaway animation in a single HTML file.
Parameters:
Output size, generation time, token usage, cost.
Results:
Sol: 28 775 chars | 641s | 11 181 tokens | $0.33
Fable: 19 186 chars | 255s | 21 288 tokens | $1.04
Opus: 13 178 chars | 77s | 7 716 tokens | $0.18
Opus fastest, Sol heaviest output, Fable most expensive.
GPT-5.6 Sol , Luna , Terra LIVE on AnyAPI
We gave Sol, Luna, and Terra the exact same prompt: animate a cutaway of the legendary Soyuz RD-108 rocket engine inside a single HTML file.
Performance & costs:
Sol: 14.5k tokens | 118s | $0.42
Luna: 5.5k tokens | 48s | $0.03
Terra: 9.0k tokens | 48s | $0.125
Sol is the powerhouse : 36KB of code, turbopump spinning, mach diamonds in the exhaust, the full museum treatment.
Terra balances speed, quality, and cost right down the middle.
Luna is comically cheap: three cents for a working engine breakdown.
Docs, guides below:
Fable 5 is back on AnyAPI
We gave Sonnet 5 and Fable 5 the exact same prompt: explain how the legendary 2JZ engine works and turn it into an animated, interactive 3D breakdown inside a single HTML file.
Performance & Costs:
Sonnet 5: 37.2k tokens | 400 sec | $0.37
Fable 5: 18.8k tokens | 238 sec | $1.01 (inc. 2k reasoning)
Sonnet 5 optimized for cost, while Fable 5 cut the generation time almost in half. Honestly, both models did an absolute hell of a job rendering the engine mechanics.
We'll leave it up to you to decide which output wins : let us know in the comments.
Docs, guides below:
we’ve recently added support for the following models:
OpenRouter Fusion
Nex N2 Pro
Nvidia Nemotron 3 Ultra 550B
Nvidia Nemotron 3 Ultra 550BQwen 3.7 Plus
MiniMax M3
Step 3.7 Flash
Claude Opus 4.8 Fast
Claude Opus 4.8
Qwen 3.7 Max
Grok Build 0.1
Gemini 3.5 Flash
4
463

Introducing Gemma-4-31B-it-Pearl on AnyAPI
Pearl Research Labs’ instruction-tuned checkpoint of Gemma 4 31B is now live, powered by the @prlnet Proof of Useful Work protocol. Experience fast, decentralized AI inference via our seamless API.
Driven by Pearl Research Labs, this integration bridges ML and blockchain. Every API request utilizes a decentralized network where nodes run the model and mine $PRL through their innovative PoUW mechanism.

8
491
did you know Claude Code can run on *any* AI model?
set ANTHROPIC_BASE_URL to your API aggregator ( AnyAPI , OpenRouter , Together AI , etc.)
boom - now you've got Kimi K2.6 , GPT-5.5 , Gemini 3.5 , DeepSeek V4 , Llama 4 running through Anthropic's agentic terminal
switch models mid-session with /model, no restart needed

1
326
