
SVP Product AlphaSense
Manhattan, NY
Joined May 2009
- Tweets99
- Following156
- Followers271
- Likes1.2K


Interesting framing - this is exactly how we designed our SuperAnalyst MCP. Think of it as an intelligence engine efficiently producing exactly the right context for any investment research use case, continually optimizing itself in real time.
Context is the true bottleneck to greater AI adoption in finance. Let your agent point its tokens on the problem you’re solving, not on extracting data from hundreds of sources and millions of documents and data points. alpha-sense.com/resources/pr…


I much prefer the concept of bringing context to the agent vs. bringing the agent to the context.
What do I mean by that?
Rather than asking an agent to discover its own context through tool calls, file exploration, and RAG queries…
Build a pipeline that understands your agent use cases and arranges for the relevant context to be materialized just in time and kept up to date.
Then have your harness match each use case to the context it needs.
1
13
867
Today @AlphaSenseInc, we're launching the SuperAnalyst MCP, putting SuperAnalyst to work wherever your agents run. Rather than one more data pipe for your agents to brute force there way across, SuperAnalyst MCP allows them to delegate research to the world's best research system - thousands of sources, market-leading search, purpose built AI - so your agent spends its tokens on the problem you actually want solved.
We measure dramatically higher quality at 3x lower cost with ever claim cited to its source down to the sentence.
SuperAnalyst has become the platform for technology teams to automate complex investment research and build institutional grade market intelligence applications. Highly encourage folks to check it out: alpha-sense.com/resources/pr…
SuperAnalyst driving another acceleration in token consumption at AlphaSense given step change in complexity of work automated and executed. Product work now is in teaching all users how to harness that power.

Updated Token Consumption Tracker
For Anthropic S-1 day, breaking out the surge in Ant tokens based on usage on AlphaSense
Update your models accordingly

1
8
679
The obvious way to bring both sides together is to allow distillation for open weights models by American companies.

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…

610
Meta being back in the open weights game is a very big deal. There have been 3 major training (SFT/RL) periods since the ChatGPT moment:
1. 2023 when the closed models weren't good enough for many use-cases and weren't enterprise ready (ZDR, security, latency, hyperscaler support). AlphaSense was big on fine-tuning (including on Llama 2/3) in this period and it helped us launch features like Smart Summaries at sufficient reliability. But as closed models accelerated (Sonnet 3.7, GPT-4o and especially reasoning models like o1) the market including AlphaSense re-focused around the labs to power features like Generative Search and Deep Research (still maintained custom models for narrower data processing and ranking use-cases).
2. 2025 when the labs released their fine-tuning endpoints and a number of startups hyped these offerings. This was always a flash-in-the-pan and we didn't take it seriously.
3. Right now. The ecosystem around training is fully here with data generation, RL infra and American open weights models all feeding off each other. Once again at AlphaSense, we see a massive opportunity to increase the quality, reliability and efficiency of our AI offerings by training custom models. In particular we are very focused on models for Search - specifically context collection across our qualitative and quantitative tools and data which continues to be the biggest bottleneck and opportunity for progress in AI in Finance.

Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats to @alexandr_wang and the MSL team for all your great work on these models.
1
2
644
This is correct and we are already seeing glimmers of recursive self-improvement from internal use accelerating SuperAnalyst development. But @AlphaSenseInc we are taking this idea even further.
In Finance, a growing share of our workload leverages recurring structures: supply-chain relationships, channel check signals, and the key debates around companies, industries, and cross-sector themes.
Today, an agent reconstructs these from hundreds of documents, per user, per query, at run-time. Once you see agent output as a knowledge asset, a strategic question follows immediately: why wait for the request?
We're deploying agents that pre-compute them as first-class, queryable datasets: supply-chain graphs assembled across filings, transcripts, and expert calls; channel-check syntheses coordinated by AI interviewers; key-debate ledgers maintained per ticker with the bull and bear evidence attached, updated as new documents land.
Our SuperAnalyst starts from the pre-computed structure and spends inference only on the delta, each new question, new document, new angle leading to better consistency, lower latency, and cleaner citations as side effects. Just like standardized fundamental data helped analysts avoid extracting the same data manually from unstructured company disclosures, we are now structuring the next major layer of analysis that everyone has been doing independently.


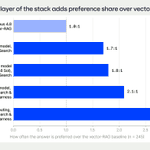
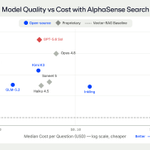
We benchmarked every major LLM on 245 hard finance questions.
The takeaway: The bottleneck in our industry isn’t reasoning; it's retrieval. Same model, same content, AlphaSense Search vs Vector Search MCP: 3x cheaper, answers preferred 2.8:1.
And the model that came out on top @OpenAI's GPT-5.6 Sol (and cheaper than Kimi K3!) 🧵

Standard RAG tools break down exactly when questions get complex. Not a retrieval failure, an architecture one. Filtering and synthesizing are different cognitive tasks; forcing both into one pass kills quality. Read more: alpha-sense.com/resources/pr…

1
119
Huge advancement here with our new multi-agent GenSearch that leverages qual + quant tools, monitors proactively and generates real work products. We’re building an AI SuperAnalyst that learns your specific workflows. Check it out!

👟 Move fast or be right. It's an impossible decision you face everyday. But in 2026, why do you have to choose?
Fragmented workflows and switching from tool to tool is time consuming and hampers your productivity. You need answers you can trust and actionable intelligence.
The next generation of Generative Search with AlphaSense is designed to be your research partner, not just a search tool. Let our SVP, Product @cackerso explain why.
⬇️
alpha-sense.com/resources/pr…

I just bought my ticket to @Signalconf happening in SF, May 24-25. I hope to see you there. bit.ly/1nZAATE
The Promise of Artificial Intelligence Unfolds in Small Steps flip.it/FnjgW

1
Great piece on applying Design Thinking at scale
ibm.com/blogs/watson/2016/02… via @ibm