

over-analyze everything.
USA
Joined March 2025
- Tweets560
- Following220
- Followers2.4K
- Likes261




catching up on JEPA research papers feels like reading a 10-year saga that Yann is unfolding
1
16
838


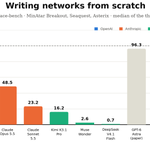
i created a open benchmark on "weight-space programming" and GPT-6 Astra scored the highest at 96.3 against baseline (500M PPO).
runner up: GPT-6.1 Sol, Claude 5.5
my main curiosity was how other LLMs write weights from scratch rather than editing them or "reading them".
so this benchmark only measures the model's ability write new weights from scratch.
full disclosure, im pretty skeptical about this still - but i think it's crazy to just let this idea go by. we need the ecosystem to run with it and see its limits, and train foundation models to optimize this.
github repo: github.com/eomcaleb/weight-s…


We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Caleb Eom retweeted

this is such a well done and beginner-friendly intro to how CUDA works at the high level and will help mold your brain around how kernel engineers think about performance for any given problem. no code at all, just dark theme diagrams!
link below

CUDA explained from a first principles perspective.
Turns out, it's more than just a collection of kernels but it's a huge ecosystem and a huge rabbit hole to dig into.
@NVIDIAHPCDev @NVIDIAAIInfra
ok im now back to being stupid again. CUDA is a huuuuge rabbit hole.
xitter.twitterapi.xyz/calebfoundry/status/21…


holy crap i finally understand CUDA.. finally at the peak of mount stupid, now heading towards valley of despair..
2
13
483


