Context.dev (@getcontextdev) header
Context.dev (@getcontextdev) profile picture

One API to scrape, enrich, and understand the web. Trusted by 20K+ developers.

Joined May 2024
Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)Photo by Context.dev (@getcontextdev)
Every agent deserves accurate and fairly-priced web data, so we raised 9M to make it happen. To celebrate we're giving away 50k credits to every sign up today. Let us know what you end up building!
We raised $9M to give your agents the internet. Led by @generalcatalyst, with @orangecollectv and Robinhood Ventures. Search, scrape, crawl, monitor with one API trusted by 800+ customers. We’re making it ridiculously easy to build with web data.
3
22
2,536
Company Search now returns social profile URLs alongside company results, including LinkedIn, X, Instagram, YouTube, and more, when available. Enrich your CRM, research prospects, or build company directories with fewer follow-up searches.
1
1
2
23
1,931
Context.dev retweeted
Kevin’s first biz SlideSpeak was one of our first 30 customers (still live and highly profitable) Now with Doop he’s again chosen context.dev to power brand kit generation and scraping (customer #834) It’s very rewarding to see customers choose us repeatedly over time Everyone check out Doop if you want a banger paper alternative!
Just dropped Component support in Doop. Agents can now create and re-use components while they design.
4
1
16
1,162
Customers got weird fonts? We got you. 🧟 Don’t make them rebuild their brand during signup. Customers use Context.dev to generate branded emails, slide decks, and websites without making users enter their brand details manually. Less setup. Faster time to value.
3
2
1
13
803
Context.dev retweeted
Scored my first #1 place on a benchmark working for @getcontextdev And not done climbing yet Benchmark (Needle): Correct retrieval of scholar articles
3
1
1
11
437
Context.dev retweeted
Great day of building at the @getcontextdev office with @kgoedecke, @oliviersm199, @karatzas_thomas! Thanks @mynameisyahia and @triekki for having us!
3
2
1
15
1,595
Thanks to @getcontextdev new users have the option of matching the FermentIQ UI to their brand. It scrapes their logo & info (brewery name, beer brands etc and colors) and offers to match the UI to their brand. Neat!
1
2
163
Context.dev retweeted
Co-hosting a chill coworking afternoon at the @getcontextdev office. Thanks for organizing @mynameisyahia!
4
3
1
54
5,039
Context.dev retweeted
Continued working on Connectors page for the dashboard, with every brand logo pulled from @getcontextdev
1
1
6
248
context.dev is the #1 web data api
🤝 Paid partnership · 🤖 Made with AI
9
3
2
51
9,264
Context.dev retweeted
Replying to @mynameisyahia
sold! switched over to @getcontextdev in a matter of minutes! it’s faster than @firecrawl and they actually allow discounts for devs on monthly plans (found out after the fact it was only annual). thanks @mynameisyahia for your help!
2
1
4
450
Context.dev retweeted
we at Nova( @supercodeai) have been using Context for: - default web search - deep search for researchers - pdf parsing - brand retrieval - news and more and it has been the best experience since day one
Introducing TRACE: Transparent Real-world Assessment of Content Extraction. A live benchmark of fresh URLs, updated daily. Most scraping benchmarks are instantly outdated the day they are released. To fix this, we mine the web for new URLs every day Here's how it works ↓
2
1
7
265
Every time a data provider reaches out to me, or an email validator, anything like that, my first response is, "Send me a benchmark." There is no loyalty. The race is to be the best per task or the cheapest per task, with no in-between Really appreciate the transparency that Context Dev delivers
Introducing TRACE: Transparent Real-world Assessment of Content Extraction. A live benchmark of fresh URLs, updated daily. Most scraping benchmarks are instantly outdated the day they are released. To fix this, we mine the web for new URLs every day Here's how it works ↓
7
2
9
971
Lets make AI search better
Introducing TRACE: Transparent Real-world Assessment of Content Extraction. A live benchmark of fresh URLs, updated daily. Most scraping benchmarks are instantly outdated the day they are released. To fix this, we mine the web for new URLs every day Here's how it works ↓
1
3
235
Introducing TRACE: Transparent Real-world Assessment of Content Extraction. A live benchmark of fresh URLs, updated daily. Most scraping benchmarks are instantly outdated the day they are released. To fix this, we mine the web for new URLs every day Here's how it works ↓
6
2
8
35
8,504
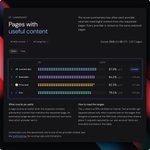
Every day at 00:15 UTC we sample ~2,500 never-before-tested pages across 9 categories and send the exact same set to Context.dev, Keenable, Firecrawl, and Exa. We measure: – Useful content rate – Latency – Cost per useful page – Why pages fail Latest sample (Nov 6): Context.dev 87.0% · Keenable 84.2% · Firecrawl 82.3% · Exa 79.1%
1
1
4
727
Everything is public: -judge prompts -historical samples -full source code We were inspired by NEEDLE’s live search evals, and brought live evals to scraping with TRACE. Try it here: trace.context.dev Check out the code: github.com/context-dot-dev/t…
1
2
470
The answer is buried in a 500-page PDF. Your customer shouldn’t have to dig for it. Context.dev PDF parsing now preserves page numbers in Markdown, so your agent can cite the exact page behind its answer. Like Yahia’s favorite toppings: pineapple and fresh cheese. 🍕
4
1
28
2,145
Enable includeNumberedPages to add original page markers to your parsed Markdown. Works with or without OCR. docs.context.dev/parse/pdfs-…
168