

Real-time web access for your AI
Joined September 2018
- Tweets255
- Following3
- Followers1.5K
- Likes154






We ran 10 searches through @youdotcom's keyless MCP server. 10 of 10 came back.
You.com is a Massive customer. Our spotlight covers its endpoints, pricing, rate limits, and the free MCP profile.

"Is web scraping legal?" depends on where you ask.
Reading public pages is generally fine. Everything around it differs by country.
How 8 countries and the EU compare:

2
5
92

Cloudflare now lets sites set rules for each AI agent, not just "bots."
New: a Personal Assistants analytics view, plus allow or block per agent.
Its advice? Allow them.

1
57
Cloudflare's post: blog.cloudflare.com/personal…
Its docs recommend Allow for personal agents: developers.cloudflare.com/bo…

21
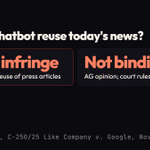
An EU court adviser says chatbots reusing news articles in real time may need publishers' permission.
Not training. Answers.
AG opinion in Like Company v. Google, Nov 3. Not binding yet.

1
65
Scrapling has 100,136 GitHub stars. Scrapy has 65,286.
Scrapy got 4.7x the downloads last month.
Stars are attention. Downloads are deployments.


1
3
158


23 AI bots from 9 operators, and how to verify each: joinmassive.com/blog/ai-craw…

1
70
Wikimedia told a federal court on Oct 29: training an LLM is likely fair use. Copying pages into chatbot answers is not.
News sites' robots.txt files draw the line the other way.

2
2
125
The brief, in the consolidated OpenAI copyright case in New York, backs neither side, and the court hasn't ruled on it.
Its fix for retrieval: follow the source's license, like Wikipedia's CC BY-SA credit. Not legal advice.
1
41
The brief: commons.wikimedia.org/wiki/F… What 49 news sites block, bot by bot: joinmassive.com/blog/should-…
37