

Maintains https://xitter.twitterapi.xyz/t.co/VoCwlJ9Eq0 / https://xitter.twitterapi.xyz/t.co/bMI9arVwcR / https://xitter.twitterapi.xyz/t.co/2agmCPOZ2t. Wrote iOS app Snapchat (2014-2020). Founded Facebook Videos with others (2013). Sometimes writes at https://xitter.twitterapi.xyz/t.co/Gyt4J9Z9Tv
San Francisco, CA
Joined April 2010
- Tweets2K
- Following284
- Followers4.2K
- Likes960




It doesn’t matter. But I said this a few years ago: Jensen is the best CEO and my personal hero. He is the person in the arena. It was true in 2012, and it is true today that he is the only CEO wakes up in the morning and is ready for his job to make GPU go brrr.
1
2
189
Is looping / repetition a real issue for GLM 5.3 Flash in practice? I never used this model for extended time, so all these are new to me.
2
3
782
The M5 Ultra situation needs to be resolved @apple and @johnternus. Every time I show people @localcodeapp, and talked about how good the performance is on M5 Ultra, people got excited, and then checked purchase option, seeing it is February for delivery. That excitement dies.
Sometimes, I just wondering: ChatGPT's DeepResearch now is low quality. Claude's DeepResearch is high quality, but its cloud agent took 1-hour and still not finished. The DeepSeek 4.1 Flash 1017 one from @localcodeapp downloaded data from FRED, ran pandas, cross check news in 54m
8
1,040
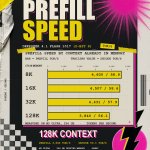
Still working on it! Felt I was overly dismissive a year ago on works people doing on LLM prefill side. Hope to clear things up!

We’re excited to welcome @liuliu, creator of Draw Things, to this Monday’s AiOS Meetup lineup (November 9)!
In LLM Prefill: What We Got Wrong, Liu will share how his team took the performance tricks behind one of the fastest diffusion engines on Apple devices and applied them to LLM prefill. He’ll cover what carried over, what didn’t, and what they learned along the way, plus a look at some of the design choices behind Local Code.
luma.com/wy0z8tek

One thing updated since this post: if the U.S. stopped building data centers now, the local option would be cheaper, for reasons: 1. less rent-seekers in the chain; 2. the cost of the device amortized by things that is not AI but useful to you.


2
446
Tried to reprod the "read NN weights directly" prompts with @localcodeapp & DeepSeek 4.1 Flash 1017. Out of the 4 games, it got 3. Unlike @simonw's run, mine got the Freeway, but not Pacman (!!!), so there are some sampling related issues (i.e. I need to run it a few more rounds)
So, if you break it down, nothing fancy (still impressive!). The size / resolution of the network is a giveaway that it should be a simple game from Atari period, and then the enumeration becomes "easier".
1
104
I shared the full trace / answer / system prompt (default of @localcodeapp) / user prompt (unchanged) in this fork: github.com/liuliu/lm_underst… Note that we didn't disable any tools (use the full default sys prompt), the user prompt is enough to forbid the model to not use any tools.
99


Liu Liu retweeted

Have been playing around with local this weekend. the speed of the model is quite impressive and it runs much faster than my home grown mlx stack
So much so, that I am replacing my local model server with one that can leverage the model repositories from draw things and local code
If you want to run models locally, this is the best way that I have found to maximize intelligence and speed

🙏 A few things to add: the app is open-source: github.com/drawthingsai/loca…
Yes, we do our own inference engine, but that is the only a part. To me, the most exciting one is to use App Sandbox so your trust is on Apple, not us. And you don't need to download any other tools!


