

Official @perplexity_ai developer account for real-time API updates.
Joined March 2025
- Tweets194
- Following40
- Followers8.3K
- Likes263
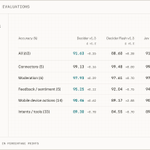
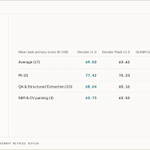


We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models.
v1.3 adds locate, a new feature that extracts spans based on type or instructions.
Now available in our Decisions API, @huggingface, and @OpenRouter.
perplexity.ai/hub/blog/perpl…
pplx-decider-v1.3 and pplx-decider-flash-v1.3 are free on @OpenRouter until November 19.
openrouter.ai/perplexity/ppl…

Both models are available on Hugging Face under Apache license:
huggingface.co/collections/p…
1
2
200
Every Agent API effort level now costs less with the same or higher research quality.
Effort levels are bundled agent configurations, optimized for specific tasks.
A new ultra level is available for the most demanding, long-running requests.
pplx.ai/effort-levels
ultra runs three research agents in parallel and a fourth orchestrates, assigns tasks, and merges the findings.
Every child agent runs its own research loop with a separate context, using its own model, tools, and step budget.
1
11
886
Set effort to fast, low, medium, high, xhigh, or ultra to use the updated configurations in your workflow.
Read the docs: docs.perplexity.ai/docs/agen…

7
631
The Decisions API can now search the web before it answers.
A decision model returns a probability, but only knows what it saw in training, and your state. Add "mode": "web_grounding" and Fast Search runs one query per question, so pplx-decider-v1.2 answers from today's web.

When enabled, Fast Search results join state as evidence before the decision model answers. Pass a URL as the state to ask about a page.
Requests are $0.001 per search and $0.02 per 1M tokens.
pplx.ai/web-grounded-docs
1
16
1,062
Use web grounding to fact-check a list of claims, determine whether a pinned package has a newer stable release, or flag accounts with a new CEO, an acquisition, or layoffs.
pplx.ai/web-grounded-cookboo…

8
813
Introducing pplx-embed-v2-context: open-weight vision-language embedding models in 9B and 0.6B.
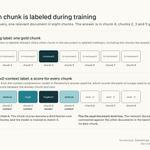
Both return one int8 vector per document, or one per chunk that sees the whole document.
Read the paper, written with @turbopuffer: arxiv.org/abs/2610.38854

Both models also run in non-contextual mode: one embedding per document, no chunking.
On ViDoRe-V3 markdown, the 0.6B is the strongest sub-1B model, chunked (contextual) or unchunked (non-contextual). The contextual 9B with 128-token chunks is second only to voyage-context-4.
1
5
897
The 9B was trained only on text, yet it outperforms the leading dense retrievers on visual documents.
With two 1024d embeddings per page, it beats Nemotron-3.5-Embed-8B on ViDoRe-V3 with a 4x smaller index.
pplx.ai/hf-embed-v2-9b
pplx.ai/hf-embed-v2-0.6b

You can now run pplx-decider-flash-v1.2 locally on your Mac, without an API key.
Decider for Mac is an app that runs the 4B decision model on device. Ask a question about text or an image and get a probability back, all on your machine.
pplx.ai/decider-for-mac
After a one-time 5.8 GB model download, the app serves the Decisions API at localhost:8080/v1/decisions.
Use it to label files, route messages, check screenshots, or run a pre-commit check, all without data leaving your Mac.
Requires a Mac with Apple silicon, macOS 13 or later, and 16 GB of memory.
pplx.ai/decider-for-mac