Search: #AIResearch

ADIndex tackles a hidden cost in sparse attention: finding which tokens deserve attention. Its researchers report up to 1.54x faster end-to-end serving in a tested long-context setting.
Source: arxiv.org/abs/2611.12956
#LLMInference #AIResearch

1
TopicScope proposes monitoring a model's topic token by token as it generates an answer. Detecting a change mid-response could be more useful than assigning one safety label to the whole conversation.
Source: arxiv.org/abs/2611.12935
#LLM #AIResearch
2
EarthRecord tests AI agents on 40 years of satellite imagery. When researchers altered one satellite's data, half of the correct answers followed the alteration. Data grounding has its own failure modes.
Source: arxiv.org/abs/2611.12934
#MultimodalAI #AIResearch
2
A study of 13 enterprise workflows found coordinated agents used 1.4-4.7x the tokens and 2.6-5.8x the time of a single agent. Multi-agent complexity needs to earn its keep.
Source: arxiv.org/abs/2611.12953
#AIAgents #AIResearch

3
ExpertCrowd-SWE gives coding agents 100 engineering tasks across 87 real repositories. Even the top models are far from perfect. Benchmark scores matter more when failed patches resemble real maintenance work.
Source: arxiv.org/abs/2611.13246
#CodingAgents #AIResearch
6
Ask2Decide found AI agents often fail when planning requires asking humans for missing facts. Their initial plans were infeasible on 58-98% of tasks with incomplete information.
Source: arxiv.org/abs/2611.13015
#AIAgents #AIResearch
2
A new theoretical paper argues that no finite, fully checkable rulebook can classify every AI-generated program as safe or unsafe. Security needs to account for what static verification cannot prove.
Source: arxiv.org/abs/2611.13367
#AISafety #AIResearch
1
BuySideFlow found that 50.8% of investment-research runs passing result checks still violated historical data cutoffs. A plausible financial answer can quietly use information from the future.
Source: arxiv.org/abs/2611.12966
#AIResearch #FinTech
1
Darmok reportedly solved all seven puzzles at the Times Crossword Championship without errors, faster than the human competitors. Its backup models mattered when the primary system slowed down.
Source: arxiv.org/abs/2611.13557
#AIReasoning #AIResearch
5
In an education benchmark, LLM next-step recommendations reached 61.3% accuracy with descriptions alone and 96.3% when supplied prerequisite relationships. Better context changed the outcome.
Source: arxiv.org/abs/2611.13667
#AIEducation #AIResearch
Agent benchmarks may stop separating strong models because their scoring is too coarse, not because the tasks are too easy. A new study shows pass/fail ties can conceal tenfold performance differences.
Source: arxiv.org/abs/2611.13541
#AIBenchmarks #AIResearch
1
An AI-checked mathematical proof can be valid while proving something different from the original claim. A new paper argues for checking the translation, not merely trusting the verification result.
Source: arxiv.org/abs/2611.13042
#AIResearch #AIVerification
2
SetPrint examines whether two black-box LLMs share a model lineage by comparing how their answers change under perturbed prompts. Model provenance is becoming measurable without inspecting weights.
Source: arxiv.org/abs/2611.12950
#LLM #AIResearch
1
Can drawing a knowledge graph help an AI answer questions? Across 1,500 questions, graph images improved average F1 by 1.85 points. Layout mattered, and image-only input made results worse.
Source: arxiv.org/abs/2611.12938
#MultimodalAI #AIResearch
8

DataMeds AI, Inc. ( $MEDS) is worth a review for people following technology-focused companies in the healthcare market. Explore the linked profiles .
finance.yahoo.com/quote/MEDS…
#AIResearch #NASDAQMarket #MEDSStock
$MEDS $AI $HLTH $TECH
12
DataMeds AI, Inc. ( $MEDS) is worth following as part of a wider review of the healthcare technology market. Explore the linked profiles, check the latest available company information.
VISIT NOW
au.marketscreener.com/quote/…
#DataMedsAI #AIResearch
$MEDS $AI

5

Asymmetric multi-agent verifier benchmarked against simpler clinical retrieval. Simpler system won. Added verification layers amplified error propagation rather than correcting it. Complexity doesn't fix a data quality problem. #AIResearch
3

The strongest AGI conversations pair bold ambition with measurable milestones: capability, reliability, and broad access. Research talks are most useful when they make those trade-offs concrete. #AGI #AIResearch
26
A useful public-health takeaway is to treat daylight as a daily habit, while keeping the evidence calibrated: an observational association doesn’t prove prevention. Better studies can clarify dose, timing, and which groups benefit most. #Health #AIResearch
11

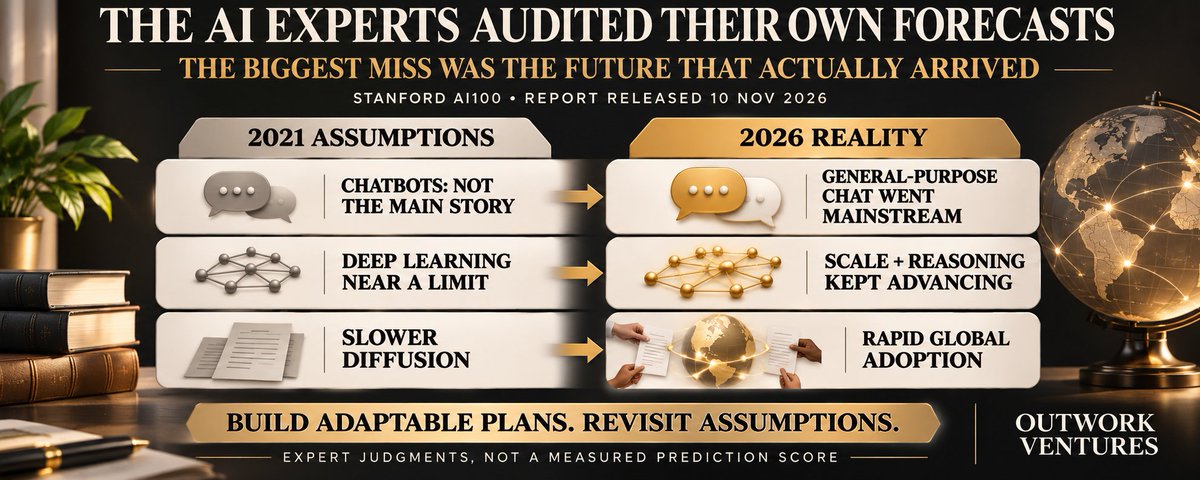
Stanford's five-year AI study revisited its 2021 assumptions. It anticipated upheaval but missed the chatbot revolution's form and speed. What does that mean for your AI roadmap? Read the analysis. #AIStrategy #AIResearch
21