
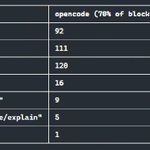
Anyone knows why @OpenDesignHQ's DeepSeek thinks and outputs more even though (based on my benchmarks) it doesn't seem to be quantized compared to OpenCode? The screenshot below is an average of 9(x2) benchmark runs, each taking more than an hour.

15