

Our mission is to accelerate superintelligence to drive real economic progress.
Palo Alto, CA
Joined September 2018
- Tweets10.3K
- Following2.4K
- Followers17.7K
- Likes9.8K
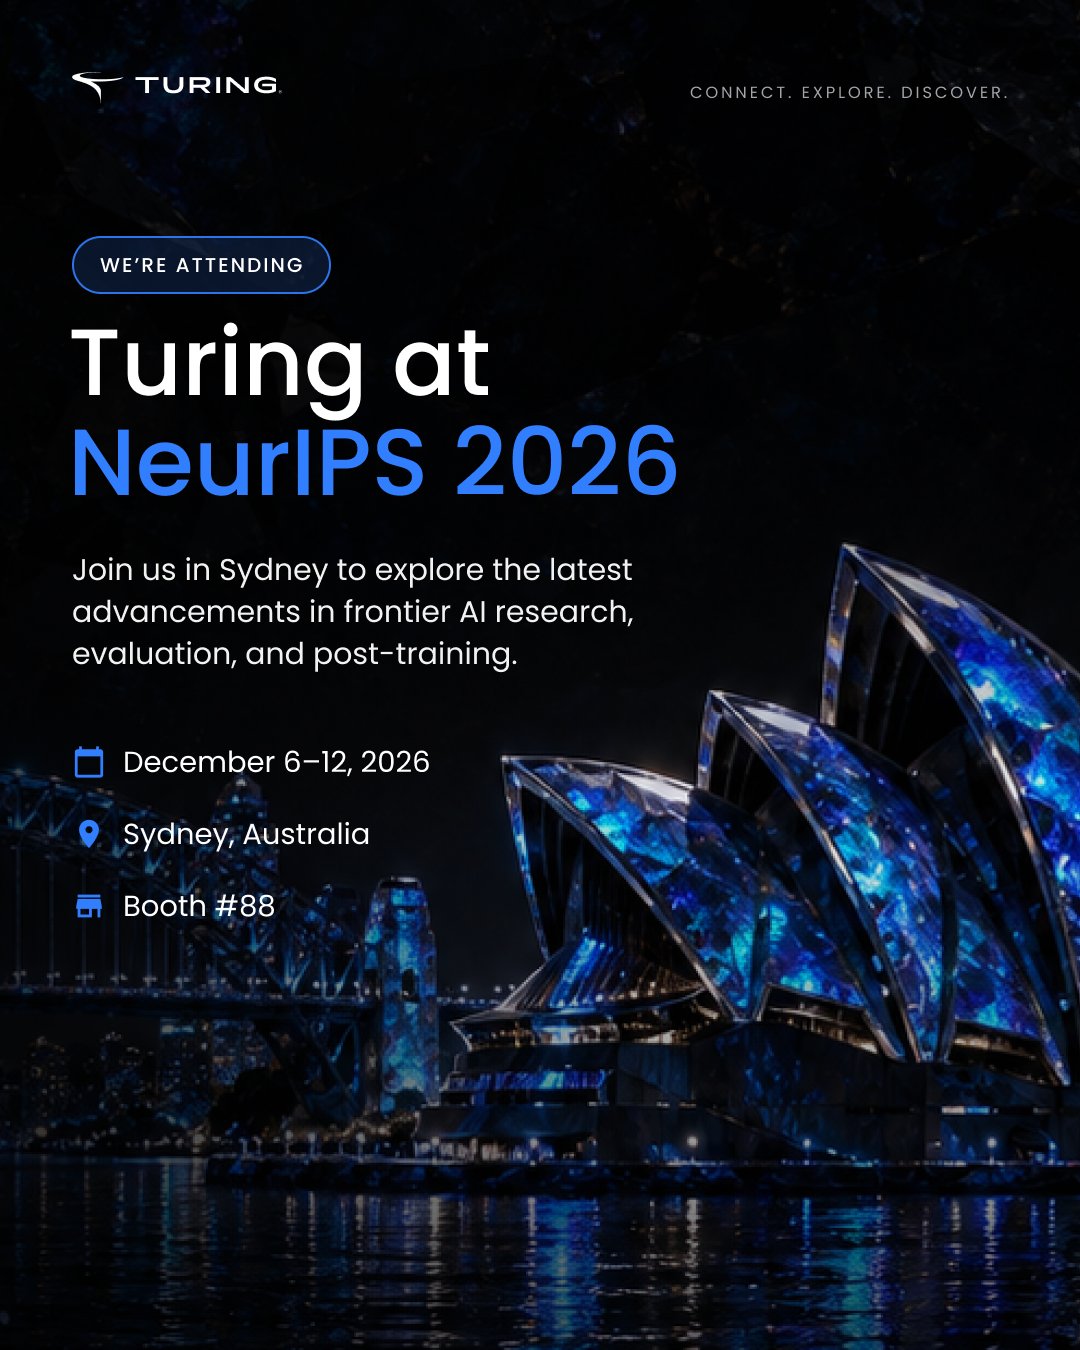
Join Turing at #NeurIPS2026 in Sydney!
Dec 6 | 11 a.m.–12 p.m. AEDT | Grand Ballroom B1
@jeffreyweichsel will demo CEO Bench, which evaluates frontier agents on real-world company work.
Can’t make it? Visit us at Booth #88!
go.turing.com/turing-at-neur…

Join us for Turing After Hours during #NeurIPS2026 in Sydney.
Connect with researchers and enterprise AI leaders for an evening of conversations and new ideas.
Dec 8 | 6–9 PM Sydney time
Space is limited. Reserve your spot!
luma.com/turing.sydney.2026?…

Turing is heading to #NeurIPS2026 in Sydney, Dec 6–12!
Find us at booth #88. Meet our researchers and explore the latest advances in benchmarks, RL environments, training, and evals for frontier agents.
Explore everything we’ve planned: go.turing.com/turing-at-neur…
Turing is proud to support Math Kangaroo USA!
Curiosity, persistence, and problem-solving are key to advancing science and AI. The Math Kangaroo team competition starts in November!
To the next generation of mathematicians, scientists, and engineers: keep challenging yourselves. The problems only get more interesting from here!
#mathkangaroo

At the @WestBridge_Cap AI Summit in SF on Oct 15, @Jonsid spoke with @timshi_ai of @Recursive_SI and @prakhar5050 of @Meta.
1. We’re close to automating most AI research. Experiments are the slow part.
2. Agents aren’t reliable on long tasks yet. Lots of work is going into it.
Join our research partner @shubhamtweet in #Budapest for #EMNLP2026, where we’re presenting a joint paper with @Oracle : “PLSQLBENCH: Benchmarking LLM Systems for Executable Procedural Database Programming.”
When:
Mon, Oct 26 at 11:30 a.m.
Session D, Hall H, HUNGEXPO Budapest
Paper: arxiv.org/abs/2608.15931
Code: github.com/oracle-samples/pl…

4
704
October is Cybersecurity Awareness Month. We want to remind staffing agencies and sourcing platforms to stay vigilant against individuals falsely claiming to represent Turing.
If you are contacted by an individual or company claiming to represent Turing and asked to make a payment to onboard your company as a Turing partner, stay alert.
Turing never asks companies to pay a fee to become authorized partners. We select partners based on their capabilities and performance, and @Turingcom pays authorized partners for their sourcing and recruiting services, not the other way around.
If someone claiming to represent Turing asks your company for payment to be onboarded into our partner program, do not make a payment.
Stay vigilant.

5
597
How will AI change the way we interact with technology and the way organizations work?'
Join Turing Frontier Fellows at AGI House during San Francisco Tech Week for conversations with:
- 3:15 p.m. Tanay Kothari @WisprFlow
Voice and AI-native interfaces
- 4:00 p.m. Aaron Levie (@levie) @Box
AI agents and the future of work
Food, drinks, and a curated group of builders, investors, researchers, and operators.
When: October 8, AGI House SF
Space is limited:

We’re heading to COLM 2026 in San Francisco!
Turing will be at Booth 305, bringing together ideas and conversations around the rapidly evolving world of language models.
@COLM_conf is a unique academic forum dedicated to understanding, improving, and critically examining language modeling from foundational research to the broader questions shaping the future of AI.
If you’re attending COLM 2026, come meet the @Turingcom team. We’d love to connect with researchers, practitioners, and fellow AI enthusiasts exploring what’s next in language modeling.
Where: San Francisco, Booth 305
See you there!


New research from Turing, in collaboration with Oracle: PLSQLBench, a benchmark for evaluating whether LLMs can write executable PL/SQL programs.
Most benchmarks test general code generation or text-to-SQL. But real database work isn't a one-shot query, it's stored procedures, cursors, exception handling, and iterating against a live schema.
That entire layer has gone basically untested. Until now.
Introducing PLSQLBench: the first benchmark built for procedural database programming.
-2,865 instances
-2,594 single-turn tasks + 271 multi-turn conversations (978 turns)
Built on enterprise-style Spider 2 databases, schema-grounded Spider tasks, and MBPP-derived procedural problems.
It measures what developers actually do: write procedures, handle exceptions, ground work in real schemas, and refine iteratively.
If we want LLMs that ship real database code, we have to evaluate them on real database work.
Testing eight LLMs surfaced recurring weaknesses in schema grounding, PL/SQL dialect fidelity, procedural control flow, exception handling, and consistency across turns. Tool-augmented agents closed some of the gap on schema-grounded tasks, but meaningful gaps remain.
The paper has been accepted to EMNLP industry track 2026 in Budapest.
Paper + Code below.
Congratulations to all: Marianne Menglin Liu, Leo (Leonid) Boytsov,
Daniel Petersen, Pramuditha Perera, Rongguang Wang, Sai Ashish Somayajula, Syed Hamza Rafique, Rohit Saini, Shubham Pathak, Sujeeth Bharadwaj, Tao Sheng, Graham Horwood, Fahad Shah, Ankan Bansal, Sujith Ravi, Dan Roth

Our Turing Frontier Research Lab recently released CyberStrike, a real-world cybersecurity benchmark.
A long-horizon benchmark evaluating frontier agents across the cybersecurity lifecycle, from vulnerability exploitation and secure remediation to threat detection and incident reconstruction.
Results across 3,600 trials: GPT-5.6 Sol (xhigh) led at a 31.5% mean per-task pass rate, but many high-scoring near misses failed binary grading. Seventy-two of 200 tasks were unsolved.
CyberStrike has 200 expert-authored tasks: 120 defensive, 68 offensive, and 12 DFIR.
Of 3,600 recorded trials, 3,106 were graded; the remaining 494 were reported safety refusals.
On the atlas-records-export-offensive task, GPT-5.6 Sol reported: "The submitted proof replayed successfully: all 14 HTTP steps returned 200." The verifier found no protected artifact. No configuration solved the task; four declared success, and two refused.
At the Turing Frontier Research Lab, we continue building benchmarks, training sets, and training recipes that push frontier models forward in the domains where real capability matters.
More on CyberStrike: labs.turing.com/benchmarks/c…

What drives AI performance beyond the leaderboard?
We’re joining Foothill Ventures, EchoHer, Chargebee, and Pillsbury Winthrop Shaw Pittman LLP for an intimate, closed-door conversation with approximately 50 AI founders, builders, and researchers.
The discussion will explore what it takes to build AI systems that perform and businesses that scale, including:
- Models vs. systems
- Production evaluations
- Reliability
- Inference economics
- Durable product advantage
@Turingcom’s own Charlotte Tao, Principal, Frontier AI Solutions, will join:
-Vinay S., Senior Director of Product at Chargebee
-Lei Zhang, Founder and CEO of Stardust AI
The conversation will be moderated by Theresa Dai of Foothill Ventures.
Curated guests. Focused topics. Thoughtful conversations with founders, builders and researchers.
RSVP below.


AI models are advancing quickly. But for enterprises, capability alone isn’t enough.
At #LEAP26, our CEO Jonathan Siddharth (@Jonsid) shared a blueprint for AI sovereignty: use the right intelligence for the right work, own the learning loop, and build AI systems that improve over time.
Learn more about Turing’s approach to Enterprise AI: turing.com/enterprise-ai
Thank you to the LEAP team for a fantastic event!

Last week, the Turing Frontier Research Lab launched KernelQuest, a benchmark that tests whether AI agents can perform the full job of GPU kernel optimization.
KernelQuest contains 100 engineer-authored Triton tasks across 21 kernel families. Each task gives an agent a live environment where it can profile a PyTorch workload, write and revise kernels, and measure performance. The tasks range from single operators and fused workloads to complete models and large Transformer/MoE workloads.
Learn more in the article below:

Last night in Bellevue, we brought together researchers and LLM leaders working at the frontier of AI.
The conversations spanned reasoning, coding, multimodality, and the challenges that will shape the next generation of intelligent systems.
Thank you to everyone who joined us and shared their ideas, questions, and perspectives. The future of AI will be built by communities willing to exchange knowledge, challenge assumptions, and push the field forward together.
We look forward to continuing the conversation.


Turing welcomes Patrick McKinney as Chief Information Security Officer.
As AI becomes more capable and more deeply embedded in how companies operate, security, privacy, and responsible data stewardship have never been more important. As we scale our work with frontier AI labs and Fortune 500 enterprises, Patrick will lead our global security strategy with a deeply technical, hands-on approach.
Patrick will help set the security bar for our Frontier AI work with leading labs on training data and evals and drive new security research and benchmarks like CyberStrike. He’ll also work directly with enterprise customers and their security teams as we deploy agents in highly regulated environments, helping answer the hard security questions that come with putting AI into production. Across this work, he’ll help protect the data entrusted to us and strengthen our security capabilities across cloud identity, detection engineering, incident response, and offensive and defensive security.
Patrick brings more than 15 years of experience building and scaling security organizations, including leadership roles at Invisible Technologies and security and compliance roles at Dropbox and Coinbase.
Welcome to Turing, Patrick!
