

Making Open Source Ai Win 🩷
Remote
Joined May 2023
- Tweets10.1K
- Following2.6K
- Followers4.4K
- Likes24.1K
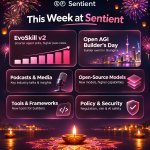




Agent improvement has relied heavily on manual prompt iteration, hand-written skills and expensive model-level changes.
EvoSkill v2 introduces a different workflow: an automated, multi-agent pipeline for evolving the instructions around an agent while keeping its underlying model and runtime unchanged.
Benchmark setup, repeated task execution, failure analysis and skill revision become parts of one structured loop.
The important engineering detail is that the system can learn from execution traces and turn recurring failures into reusable instructions.
You can improve the agent's working process without retraining its model.
@SentientAGI
@sentient_found
@SentientEco
@abhishek095

EvoSkill v2 uses a three-agent system to improve your own agent without touching the model:
1) Benchmark adaptor builds a plugin from your grader, data, and plain-language description of the benchmark.
2) Solver attempts each task three times.
3) Evolver reads attempts and rewrites skills each round.

2
3
85
1/2 | Benchmark Adaptor: removing the setup bottleneck
A skill optimizer is only useful if it can work with the benchmark you care about.
EvoSkill v2 addresses the setup friction with its Benchmark Adaptor.
You provide:
- A plain-language description of the benchmark
- The task data and split
- A grader
The Adaptor converts these into a frozen, hashed benchmark plug-in and a read-only reference folder.
That means builders don't have to manually translate every custom benchmark into an optimizer-specific format before they can start evolving skills.
The evaluation setup is established before the optimization loop begins.
1
1
24
Agent improvement has relied heavily on manual prompt iteration, hand-written skills and expensive model-level changes.
EvoSkill v2 introduces a different workflow: an automated, multi-agent pipeline for evolving the instructions around an agent while keeping its underlying model and runtime unchanged.
Benchmark setup, repeated task execution, failure analysis and skill revision become parts of one structured loop.
The important engineering detail is that the system can learn from execution traces and turn recurring failures into reusable instructions.
You can improve the agent's working process without retraining its model.
@SentientAGI
@sentient_found
@SentientEco
@abhishek095
EvoSkill v2 uses a three-agent system to improve your own agent without touching the model:
1) Benchmark adaptor builds a plugin from your grader, data, and plain-language description of the benchmark.
2) Solver attempts each task three times.
3) Evolver reads attempts and rewrites skills each round.
3
5
290
The biggest challenge in open-source AI is not producing frontier research, it is translating that research into reliable, accessible primitives that developers can actually run in production.
Bringing in Julie Beliao (ex-Mozilla.ai, Google, PhD in NLP) as VP of Product signals exactly where Sentient is heading: turning breakthroughs like EvoSkill and model provenance benchmarks into standardized developer infrastructure.
Huge milestone for the ecosystem. Welcome to @SentientAGI! 🩷

Two numbers in this week’s OS AI Field Notes frame the entire market right now:
1. Anthropic’s S-1 showed ~85% gross margins on closed models.
2. The @ArtificialAnlys Progress Index shows the gap between open-weight models and the proprietary frontier has compressed to just 2 months (led by Kimi K3.1 Pro).
Rented API moats don't hold when open models catch up 60 days later at 20x lower cost.
• On-Device Scaling: @liquidai introduced LFM3, outperforming Gemini 3.5 Flash Lite on hardware efficiency.
• Enterprise Reality: @modal CEO Erik Bernhardsson made clear on 20VC why open-source inference is accelerating enterprises need custom, private deployments, not generic black boxes.
• Agent Evolution: Following Sentient’s EvoSkill v2 paper (beating Microsoft’s SkillOpt on held-out benchmarks), @sentient_found is co-hosting Open AGI Builder’s Day with Shanghai Jiao Tong University (@sjtu1896) on Nov 15.
Read the full November 6 Field Notes: sentient.foundation/news/os-…
@SentientAGI 🤌


Anthropic’s S-1 revealed ~85% gross margins, but the moat is shrinking in real time.
According to the new @ArtificialAnlys Progress Index in this week's Field Notes, open-weight models historically trailed closed labs by 4 months and the newest release, Kimi K3.1 Pro, sits just 2 months behind the closed frontier at a fraction of the cost.
When closed APIs charge premium rents for a 60-day lead, open-source commoditization is inevitable.
@SentientAGI
🧵👇
Kimi K3.1 Pro ranks just behind Opus 5.5 & GPT-6 Astra at a lower cost, @liquidai ships a new model built for on-device AI, and @ArtificialAnlys finds open weights are only 2 months behind closed models.

Look at the infrastructure shipping across this edition:
• The Frontier Gap: Kimi K3.1 Pro is matching Opus 5.5 on CAD, game dev, and heavy STEM simulations.
• Edge Efficiency: @liquidai’s LFM3 is beating Gemini 3.5 Flash Lite on-device at lower resource overhead.
• Enterprise Sovereignty: As @modal CEO Erik Bernhardsson noted on 20VC, inference hasn't peaked enterprises are choosing open weights because workflow customization and data ownership beat rented API wrappers.
1
1
63
Anthropic's S-1 reportedly shows gross margins of roughly 85%.
Meanwhile, the latest Artificial Analysis data puts the open-weight frontier just two months behind proprietary models.
That gap matters.
Kimi K3.1 Pro is closing in on frontier performance across coding, 3D modelling and financial research, while open models keep getting cheaper to run and easier to customize.
The pressure on closed AI economics is becoming harder to ignore.
When capable models can be deployed, adapted and run on your own infrastructure, enterprises gain options that a closed API cannot always provide.
Open source is becoming a serious economic force in AI.
@SentientAGI

1/2 | The capability gap is narrowing. The deployment options are expanding.
Kimi K3.1 Pro is now reported to trail the closed frontier by around two months on the Artificial Analysis Progress Index, while competing strongly across coding, 3D modelling and financial research.
Liquid AI is pushing another part of the equation: specialized models designed to deliver competitive performance on less capable devices, with lower hardware requirements.
And Modal CEO Erik Bernhardsson makes an important enterprise point in the latest 20VC episode: companies still need models they can customize and run on infrastructure they control.
Capability, inference cost and data sovereignty are converging into one purchasing decision.
1
1
50
When an AI agent fails a complex multi-step task, retrying it blindly fails ~90% of the time.
The bottleneck isn't raw model reasoning, it's missing domain instructions.
@SentientAGI Labs just dropped EvoSkill v2, outperforming @MSFTResearch’s SkillOpt and @AlibabaGroup’s SkillBoost across held-out benchmarks while keeping the underlying base model completely frozen:
• SpreadsheetBench v2: 40.4% vs. 32.7% (+7.7pts)
• \tau^3-bench banking: 51.6% vs. 46.2% (+5.4pts)
How the architecture works under the hood: 🧵👇
Introducing EvoSkill v2: a system that automatically improves AI agent skills without changing the underlying model or runtime. It tests the agent, learns from its attempts, and rewrites its instructions to improve performance.
Our new paper compares EvoSkill v2 with SkillOpt by @MSFTResearch and SkillBoost by @AlibabaGroup on held-out tasks, reporting:
+23.6pts on τ3-bench banking with no skill, using Claude Haiku 5.5
+7.7pts over SkillOpt on SpreadsheetBench v2
+5.4pts over SkillOpt on τ3-bench banking

EvoSkill v2 replaces fragmented prompt rewriting with a 3-agent pipeline on top of your harness:
1. Benchmark Adaptor: Converts plain-language task descriptions and graders into frozen task lists before any code runs.
2. Solver: Executes tasks N=3 times in isolated containers to separate persistent logic bugs from flukes.
3. Stateful Evolver: One persistent Claude Code session with direct Bash access. It actively runs scripts to diagnose failure traces, preserves full version history to roll back regressions, and stays strictly blinded to validation sets to prevent data leakage.
1
2
47
EvoSkill v2 improves agent performance without changing the underlying model.
On held-out tasks, it reached:
• 40.4% on SpreadsheetBench v2, ahead of Microsoft Research's SkillOpt at 32.7%.
• 51.6% on τ³-bench banking, ahead of SkillOpt at 46.2%.
• Both results start from frozen model weights.
The key is a system that studies failed attempts, turns recurring failure patterns into reusable skills, and tests those skills against unseen tasks.
This moves agent improvement beyond endless prompt edits or expensive retraining. The agent can accumulate practical expertise in a layer builders can inspect, version and reuse.
The full engineering details are worth studying.
@SentientAGI 🤌

1/3 | The architecture
EvoSkill v2 separates the improvement loop into three roles:
1. Benchmark Adaptor: Converts a benchmark description, dataset and grader into a fixed task setup before skill evolution begins.
2. Solver: Attempts each training and validation task three times in isolated containers, helping distinguish recurring failures from one-off mistakes.
3. Stateful Evolver: Uses one persistent Claude Code session with bash access to inspect execution traces, investigate failures and rewrite skills.
Every skill version is retained, so the evolver can revisit earlier decisions and roll back changes.
Crucially, the evolver cannot see validation or held-out tasks, their scores, or the grader.
1
2
47
Surviving fine-tuning is only table stakes for model provenance.
Look at the attack vectors addressed across these 4 papers highlighted by @sentient_found:
1. Trigger Resistance: Private-key injection that triggers verifiable responses while preventing false attribution claims.
2. Cryptographic Binding: Hash-chaining query-response pairs to protect fine-tuned LoRA adapters.
3. High Capacity: Scaling to 24,576 fingerprints without degrading model utility.
4. Merge Resistance: Ensuring the behavioral mark persists even after weights are averaged across multiple models via TIES or Task Arithmetic.
Different methods optimize for different trade-offs. Having an open, standardized benchmark to evaluate how they hold up under live evasion tests is what moves the entire open-source ecosystem forward.
Track the rankings: fingerprint.sentient.foundat…
@SentientAGI
Here are 4 fingerprinting schemes built with survival in mind:
> arxiv.org/pdf/2401.12255 - implants a private key that causes the LLM to generate specific text when used
> arxiv.org/pdf/2407.10887 - verifies ownership by cryptographically binding fingerprint prompts to their responses
> arxiv.org/pdf/2502.07760 - embeds two orders of magnitude more fingerprints than existing schemes without model degradation
> arxiv.org/pdf/2410.08604 - keeps fingerprints intact even after multiple models have been merged into one
Model provenance has to survive more than one kind of attack.
These four papers target different failure points: instructional triggers, cryptographic prompt-response binding, fingerprint capacity at scale, and model merging.
MergePrint tackles a particularly difficult case: keeping fingerprints detectable after models are merged through methods such as TIES and Task Arithmetic.
Each approach makes a different engineering bet. The question is how well that bet holds up when models are copied, modified, or combined.
That is why open, adversarial benchmarking matters.
@SentientAGI
🧵↓
Here are 4 fingerprinting schemes built with survival in mind:
> arxiv.org/pdf/2401.12255 - implants a private key that causes the LLM to generate specific text when used
> arxiv.org/pdf/2407.10887 - verifies ownership by cryptographically binding fingerprint prompts to their responses
> arxiv.org/pdf/2502.07760 - embeds two orders of magnitude more fingerprints than existing schemes without model degradation
> arxiv.org/pdf/2410.08604 - keeps fingerprints intact even after multiple models have been merged into one
1/2
Four schemes, four distinct design challenges.
Instructional Fingerprinting uses private-key-triggered outputs and supports verifiable attribution across licensing stages.
Chain & Hash cryptographically links fingerprint challenges to responses. Scalable Fingerprinting embeds 24,576 marks in a single model without degrading utility in the reported work.
MergePrint targets another failure mode: weight averaging and model merging, including TIES and Task Arithmetic.
A fingerprint that works before modification still needs to be tested after it.
1
2
55
Why does Llmmap-v4 hold the #1 spot on the Sentient Fingerprinting Leaderboard (100% Robustness | 99% Verification | 100% Utility)?
Most provenance schemes run into a wall: if you alter a model's weights heavily enough to survive removal attacks, you hurt its Utility.
Researchers Dario Pasquini (@OneRSAC), Evgenios Kornaropoulos, and Giuseppe Ateniese (@GeorgeMasonU) approached LLM provenance the way network security engineers use nmap to fingerprint an operating system:
• Active Probing: Instead of relying on fragile output watermarks, LLMmap sends as few as 8 targeted queries and analyzes the response traces to identify which of 42 open or proprietary LLM versions is running behind an interface (>95% accuracy).
• Wrapper Resilience: Designed to work even when the underlying model is masked by custom system prompts, RAG pipelines, or sampling hyperparameters.
• Zero Capability Loss: Because the model's weights aren't degraded by forced trigger memorization, baseline Utility stays at 100%.
Technical evidence of model lineage tested in the open:
• Paper: arxiv.org/abs/2407.15847
• Benchmark: fingerprint.sentient.foundat…

LLMmap, a technique developed by researchers at @OneRSAC and @GeorgeMasonU, can trace an LLM back to its likely origin: identifying which of 42 models is behind an interface with over 95% accuracy.
The highlight: it can uncover a model’s origin in as little as 8 interactions.

LLMmap-v4 brings a classic cybersecurity idea to LLMs: fingerprint the system through its behavior.
By actively probing responses, it can identify a model among 42 candidates in as few as 8 interactions, without inserting marks that degrade the model's capabilities.
Its Fingerprinting Leaderboard scores are impressive under the tested conditions:
100% Robustness. 99% Verification. 100% Utility.
Model provenance needs methods that survive real-world wrappers while preserving performance. LLMmap-v4 is a strong example of that approach.
Test the results: fingerprint.sentient.foundat…
LLMmap, a technique developed by researchers at @OneRSAC and @GeorgeMasonU, can trace an LLM back to its likely origin: identifying which of 42 models is behind an interface with over 95% accuracy.
The highlight: it can uncover a model’s origin in as little as 8 interactions.
1/2
A model can sit behind a custom system prompt, retrieval-augmented generation, few-shot examples, or different sampling settings. Those layers change its responses, but they may not erase the behavioral patterns that distinguish its underlying model.
LLMmap uses carefully designed queries and response analysis to identify those patterns. Think network fingerprinting applied to language models: probe the interface, study the traces, infer the likely origin.
1
3
39
The most ironic security story of the year is buried in last week’s OS AI Field Notes:
When @opencode suffered a security breach from a large-scale distillation attack, the closed frontier models the team used for defense started refusing to help because analyzing the attack triggered their own safety guardrails.
Meanwhile, the open-source stack is compounding across every layer:
• 72% Token Share: Open-weight models now process nearly three-quarters of all tokens on @OpenRouter.
• 20x Cost Compression: DeepSeek-V4.1-Flash-1017 outperforms GPT-5.6 Sol on Terminal-Bench 4.0 at 1/20th the cost.
• Real Enterprise Wins: Coinbase fine-tuned an open 9B model (Qwen 3.5) to cut fraud by 30%.
• Agent Infrastructure: From Google Research’s Harness² (+11.8pp pass rate lift) to Keel rethinking Git around agent "belief collisions".
And with distillation attacks escalating across the industry, testing technical evidence of model lineage inside the weights is no longer theoretical 15 schemes are now live on the Sentient Fingerprinting Leaderboard fingerprint.sentient.foundat…
Read the full October 23 Field Notes: sentient.foundation/news/os-…
@SentientAGI 🩷

Two data points in this week’s OS AI Field Notes tell you everything about where AI infrastructure is heading:
1. Open-weight models just processed 72% of all tokens on @OpenRouter.
2. When @opencode got hit by a distillation attack, the closed frontier models they used for defense refused to help analyze the breach because the attack tripped their safety guardrails.
You cannot build critical infrastructure on a black box that locks you out during an emergency.
@SentientAGI
Look at what shipped across the open ecosystem in a single week:
• Cost & Speed: DeepSeek-V4.1-Flash beats GPT-5.6 Sol on Terminal-Bench 4.0 at 20x lower cost, while Liquid AI’s LFM2.5 runs private on-device agents with just 2B active parameters per token.
• Production ROI: Coinbase fine-tuned an open Qwen 3.5 9B model to cut fraudulent transactions by 30%.
• Agent-Native Tooling: Keel built an MIT-licensed Git platform where agents merge by testing "belief collisions" rather than line diffs.
1
4
72
Open-weight models processed 72% of tokens on OpenRouter last week.
Meanwhile, @opencode faced a distillation attack, and the closed frontier models used to investigate it reportedly refused to help because their safety guardrails were triggered.
Two signals from the same week: open models are taking production share, and relying on closed APIs can introduce constraints when you need to defend your own infrastructure.
For builders, model access, cost, control and security all belong in the architecture.
The latest OS AI Field Notes from @sentient_found cover the shift.
sentient.foundation/news/os-…
@SentientAGI

The numbers make this shift tangible.
@deepseek_ai's V4.1-Flash-1017 reportedly beats GPT-5.6 Sol on Terminal-Bench 4.0 and ProgramBench at 20x lower cost.
Coinbase fine-tuned an open Qwen 3.5 9B model and cut fraudulent transactions by 30%.
Keel is rethinking Git around agent conflicts: agents can make incompatible assumptions even when they edit different lines. Its approach turns those conflicts into tests.
Models, deployment economics and developer tooling are all moving together. The opportunity is to build systems around open models that work reliably in production.
1
2
63
The hardest part of model fingerprinting is balancing three competing goals.
Go deeper, and the fingerprint may become harder to remove, but the model can lose capability. Keep the mark light, and utility may stay high while robustness suffers.
That X-shaped curve is the real engineering challenge.
The Fingerprinting Leaderboard evaluates Robustness, Utility and Verification together. A strong result has to balance all three under the benchmark's tested conditions.
Model provenance needs measurable trade-offs, not just claims.
fingerprint.sentient.foundat…
@SentientAGI
Want to top our Fingerprinting Leaderboard? Your ranking depends on three criteria, but here are the main ones you should pay attention to:
Robustness measures how well your fingerprint survives distillation, fine-tuning, and copying.
Utility measures how capable your model still is after it’s been fingerprinted.
Verification adds another test: can the fingerprint be reliably detected when the model receives a secret query?
A method can look robust on paper and still fall short if its signal cannot be verified reliably.
If you're researching model fingerprinting, compare your method across all three criteria: survival under distillation, fine-tuning and copying; retained model utility; and verification reliability.
See where your approach lands: fingerprint.sentient.foundat…
29
One of the most useful things an AI lab can do is publish evidence that its own method can fail.
@SentientAGI's Perinucleus showed that 24,576 fingerprints could be embedded in a single 8B model while preserving utility.
Then researchers stress-tested fingerprinting methods against removal attacks. Nearly all could be evaded while keeping the model useful, including Perinucleus.
That result is exactly why open adversarial evaluation matters. A provenance method shouldn't earn trust because its creators say it works. It should earn trust by surviving attempts to break it.
The Fingerprinting Leaderboard puts that challenge in public, where researchers can compare methods, inspect trade-offs and build on the results.
Read the @Investingcom feature with @edoardocontente:
investing.com/news/press-rel…
As LLM copying and distillation becomes more common, our Fingerprinting Leaderboard aims to build an ecosystem where models can be openly shared while preserving attribution and ownership.
@Investingcom explores this approach with @SentientAGI researcher @edoardocontente.
Learn more: investing.com/news/press-rel…

Embedding 24,576 fingerprints demonstrated capacity. The harder question is whether a fingerprint survives fine-tuning, distillation and deliberate removal without damaging the model's usefulness.
On the leaderboard, Perinucleus scores 45.7% robustness, 84.4% utility and 98.8% verification under the benchmark's tested conditions.
The long-term research goal is to tie the fingerprint more closely to the model's learned capabilities, so removing the lineage signal risks degrading the model itself.
That is a research target, not a guarantee against every attack. The leaderboard makes progress measurable.
Explore the benchmark: fingerprint.sentient.foundat…
2
40
Institutional gaslighting works until a community shows up with verifiable ground truth.
Proving 2,567 mangrove trees were missing in court is incredible, but the best engineering lesson in @0xsachi’s conversation with @dwddao happens right after:
When @GainForestNow built a mathematically "optimal" payment algorithm for forest communities, the locals rejected it because it ignored how their community actually worked.
Data ownership isn't enough if an outside lab still dictates the algorithm. Real alignment means the community owns the decision layer too.
@SentientAGI

A mayor in the Philippines cut down a protected mangrove forest to build a parking lot. When the community confronted him, he said it had always looked like that.
A year earlier, @GainForestNow had measured every tree there.
2,567 were missing.
The community took the data to court, and the mangroves were replanted.
My conversation with @dwddao, co-founder and chief scientist of GainForest is live on @opencommonspod.
We get into who should own nature's data, AI that helps people govern, and what open source really requires.
1. Mathematical optimality loses to human interpretability.
When @GainForestNow deployed a game-theoretic Shapley-value algorithm in Kenya to price tree data by its exact marginal value to the ML model, the community rejected it. Payouts felt random to humans on the ground. Switching to predictable fixed payouts + post-collection cleaning fixed it.
2. AI governance requires human ratification.
Using AI proxy agents to compress 100 hours of proposal reading into 5 minutes unlocks participation but without mandatory human sign-off, autonomous votes are just "AI slop grenades."
1
45
A single score on a fingerprinting benchmark is useless because any one metric is easy to game in isolation.
Model provenance is a three-way engineering constraint:
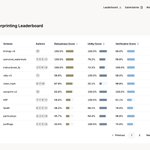
1. Bake the signal in too aggressively → You get 100% Robustness and Verification, but you degrade the weights and tank Utility (like instructional_fp dropping to 72.3%).
2. Make the signal too subtle → You preserve 100% Utility, but basic fine-tuning wipes the mark out under attack (like proflingo and stemma dropping to ~43% Robustness).
3. Make the trigger too noisy → You lose reliable Verification when testing a suspected copy.
The real test isn't scoring 100% on one column. It's surviving adversarial removal attacks without making the model dumber.
Compare all 15 evaluated schemes: fingerprint.sentient.foundat…
@SentientAGI

Why are there three leaderboard scores? Because a fingerprint has to survive attacks, preserve model quality, and remain detectable.
Push robustness too hard and utility can suffer. Prioritize utility alone and the fingerprint may not survive removal attempts.
The leaderboard makes the trade-offs visible:
instructional_fp: 100% robustness, 72.3% utility, 100% verification.
proflingo: 43% robustness, 100% utility, 75% verification.
llmmap-v4: 100% robustness, 100% utility, 99% verification.
One score hides the trade-off. Three show where each scheme stands under the benchmark's tested conditions.
Compare all 15 schemes: fingerprint.sentient.foundat…
@SentientAGI
@sentient_found
@SentientEco