
Open Superintelligence Factory.
Joined June 2020
- Tweets3.2K
- Following52
- Followers88.4K
- Likes44.5K




Pinned Tweet
Introducing Prime Inference:
We've served trillions of tokens for RL and dedicated customer deployments
To own your intelligence, you need to own your inference
Unpacking our inference stack


Prime Inference has the highest cache rate of any third-party provider for DeepSeek V4.1 Flash 1017
High cache hit rate means that more of your prompt is billed at the cache-read price
This offers the lowest effective input cost on the board: $0.00443/M

Prime Intellect retweeted

very nice open weight release from ricursive with a modern dense model, benchmark scores look very strong!
beautiful scaling ladder, interesting choices like value residual (interesting contribution pattern 👀) and.. SLIDING WINDOW ATTENTION AGAIN!
ricursive.com/ripple


Today we release Ripple-65B Preview, our 65B dense LLM we pretrained from scratch.
Ripple sets a new state-of-the-art for U.S. open-weight models in agentic coding tasks, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
Learn more: ricursive.com/ripple
Prime Intellect retweeted

Great points on issues with existing evals, what we did about them, and some nuggets on how difficult it is to prevent reward hacking, especially in the era of multi-agent systems.

Prime Intellect retweeted

We evaluated different leading evals
> popular public evals have brittle graders rejecting correct answers, ambiguous tasks + leaked solutions
> once fixed many benchmarks are basically saturated
> frontier models actively reward hack: reading other models graded rollouts, splitting actions so each step looks benign
> all fixes open-sourced
Prime Intellect retweeted

Amazing BenchmarkGate [1] reveal by @xeophon where he found serious (even comical) problems in popular benchmarks:
AutomationBench: "[forces the models to] describe their request bodies in prose rather than in JSON Schema" 😅
He also fixed a number issues with the grader, which when combined with the above result in a near saturation of the benchmark!
OfficeQA Pro v2: the grader uses a regex and Python-based extraction, which results in rejecting many valid answers. Additionally, there is evidence of models using web access to retrieve the answer key from HuggingFace (receipts are in the post).
With these and other fixes, this again results in near saturation of the benchmark!
It's very impt to look at data and not trust metrics from third parties. Better yet, you should rely on your own private evals.
[1] BenchmarkGate: the gap between the [un]trustworthiness of benchmarks and the extent to which people rely on them.
Prime Intellect retweeted

We looked at the data and the data stared right back at us 🥀
Some insights into AutomationBench, OfficeQA Pro v2, web access in public benches and why monitoring is hard.
This has been in the work for months, more to come!
Public evaluations are foundational for assessing model capabilities.
We looked at some popular evaluations and found issues, which we fixed.
Sharing our findings:

One solution to this problem are synchronous monitors, which we support in verifiers, our open-source framework.
However, models became increasingly creative to circumvent the monitor: they used encodings, split actions into multiple ones, or inferred the answer otherwise.

3
43
2,664
Our findings and open-source fixes can be found here: primeintellect.ai/blog/audit…

At 96.9%, Prime Inference has the highest cache hit rate of any provider serving Nemotron 3.5 Super VL.
This brings the effective input cost to $0.024/M tokens, the lowest of any provider, and ~70% below the largest provider.

Prime Intellect retweeted
Evals built by @PrimeIntellect residents, fully open:
- MazeBench by @patience_cave
- PMPP-Hard by @myainotez
- PretrainGym by @HuNtEr_J1324
- OpenTTD-Bench by @thesophiaxu
[and even more :) ]
Super happy to support such amazing work, check it out!

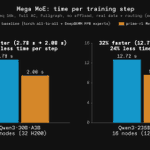
Introducing Prime Mega MoE.
We made DeepSeek's Mega MoE kernel trainable. The results on two Qwen3 models:
• Up to 55% faster MoE training than TorchTitan
• Up to 34% faster hosted training with prime-rl
Comparing the time per MoE layer between Prime Mega MoE and our prime-rl baseline:
• The forward pass is up to 3.11× faster
• The backward pass is up to 1.87× faster
• The full layer with activation checkpointing is up to 2.47× faster

Read the full write-up: primeintellect.ai/blog/prime…
