
The world's fastest AI inference and training. Try the latest open models at: https://xitter.twitterapi.xyz/t.co/jREGhLI2nj
Sunnyvale, CA
Joined July 2016
- Tweets3K
- Following272
- Followers81.1K
- Likes2K


Excited to be a day 0 @kimi_moonshot partner!


World-class AI performance, meeting everyday life. @BiltRewards 👋

A chip the size of a dinner plate, to help you book your next dinner.
@BiltRewards selected @Cerebras to power its Neighborhood OS and AI assistant, Bilt Concierge.
More than 8 million people across the US use Bilt to earn rewards on rent.
Bilt allows members to spend those rewards at 50,000+ local merchants.
Now, with Bilt Concierge, an AI agent can do it for you.
Just ask it to book a table, plan a trip or shop locally and it’s done.
With Cerebras, those services will be near instant.
World-class AI performance, meeting everyday life.
Excited to partner with @ankurjain_2 and the @BiltRewards team.

Fearless Engineering: The CS-4 is our first engineering documentary.
Through lab footage and conversations with the engineers behind each breakthrough, the film follows the creation of the CS-4, our latest wafer-scale AI system.
0:00 introducing the engineering team
1:09 Wafer-scale history
2:28 Powering the wafer
4:00 The cooling problem
4:18 Designing the cold plate
5:11 Holes in the wafer
6:33 the alignment problem
7:47 The CS-4 PRD
8:35 Designing for deployability and serviceability
11:01 Removing the motherboard
11:25 Removing internal cooling loops
11:41 inventing the power rack
12:35 A one-person lab deployment
14:03 Backpack: 50% fewer components
14:55 Connecting the compute backpack to cooling manifold
17:58 shifting Cerebras’s focus from training to inference
19:09 Building the Cerebras Cloud
20:01 CS-3 vs. CS-4 performance
20:49 3D Stacked DRAM
Moonshot just dropped Kimi K3.1 Pro. We used it to speed run online shopping.
One prompt → monitor found → checkout → order confirmed.
11.5 seconds.
Watch @Kimi_Moonshot K3.1 Pro in action, accelerated by Cerebras.
Last week, short seller @CulperResearch, published a report arguing that Cerebras wafers wear out after about two years. Nearly every financial conclusion in that report depends on that one number.
That number is wrong.
How long our systems last is a fair question, so we want to address the topic plainly. Read our response on our blog.
cerebras.ai/blog/what-it-too…

On Big Chip Club, @MilksandMatcha talks with @cdngdev, the former @OpenAI robotics intern behind this summer’s viral Astra robot-painting demo.
They discuss the creative process behind building products people want to make for themselves, why robotics needs fast inference, and what recursive self-improvement (RSI) would require.
0:00 Meet Thijs: Discord, OpenAI, and Stanford
0:47 Building a wardrobe app in a day
3:17 Making demos that cut through the noise
4:43 Whimsical and practical demos
5:25 Where good ideas come from
7:04 Teaching a robot to paint the Golden Gate Bridge
8:52 Improving the robot’s painting ability
10:34 Giving Sam Altman the robot’s painting
12:00 Why robots need fast inference
14:11 What demos should Cerebras build?
15:07 Getting started with robot arms
16:33 Recreating apps and 3D models on demand
17:56 From generated models to physical things
19:45 Inside OpenAI
20:17 What RSI means
23:11 Getting AI's benefits to everyone
24:39 Personal assistants for everyday tasks
Our ambassadors made October a massive global movement for fast inference! We hosted Cafe Compute Meetups in 15 cities:
Boston • Bengaluru • Dubai • Austin • Brisbane • Melbourne • Indore • Barcelona • Mexico City • Bhopal • Seoul • London • San Francisco • Dublin • Taipei
A massive shoutout to our incredible Cerebras Ambassadors who are growing their local AI communities around the world. 🙌
Want to bring fast inference to your community? Apply to become a Cerebras Ambassador: cerebras.ai/ambassadors


Breaking it down with Sean Lie, our CTO,
How we deploy Trillion-parameter frontier models on Cerebras

How we deploy multi-trillion parameter models at scale
Today, let's break down the math for how @cerebras:
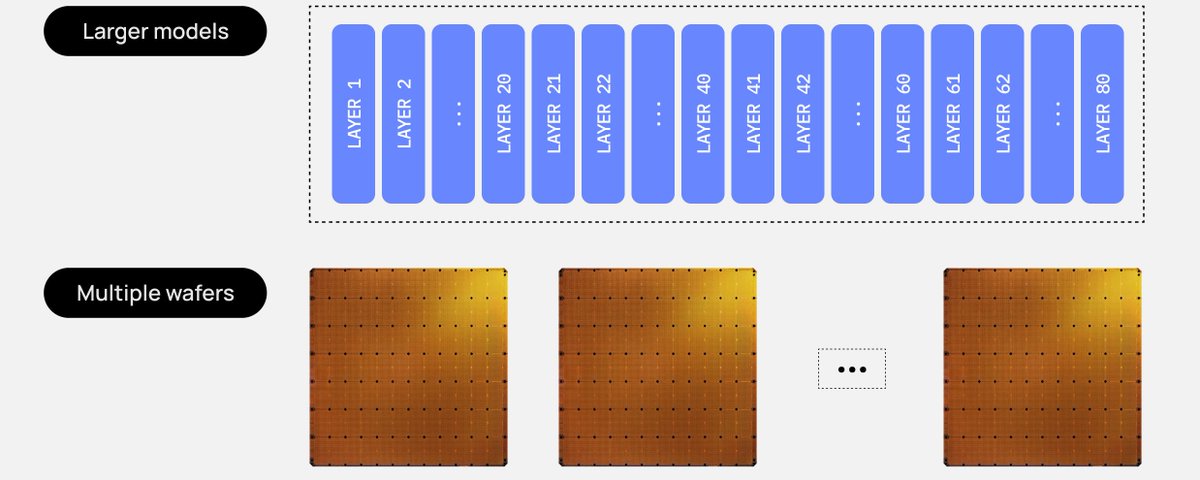
1. Fits the full model into on-chip memory
2. Maps the model across multiple chips
3. Handles a high # of concurrent requests
There's a new version of this post


Naji Jackson has spent more than 20 years supporting leaders in tech, including @alexandr_wang and @rauchg.
She joins @MilksandMatcha on @Cerebras' Big Chip Club to talk about the AI tools she has tried, why fast inference matters for making AI assistants useful, and the trust and judgment involved in the job.
0:00 Meet Naji Jackson
1:20 Being an executive assistant to some of the most influential people in tech
3:14 The craziest thing she’s had to do as an EA
5:10 Learning preferences and anticipating needs
6:56 Testing Grok Bot, Meta Muse, and Claude Cowork
9:42 What do AI assistants still need to improve?
11:27 Why AI assistants must be fast to be useful
15:28 Can AI replace a human assistant?
16:42 Personal assistants vs. executive assistants
17:37 How to hire a personal assistant
19:47 How to reach Naji
Use your existing AWS account to subscribe to Cerebras Inference: lnkd.in/gC2StuRS
The new physics of cybersecurity makes inference speed essential. Defenders now need to detect, reason, and act so much faster than attackers.
Read more about how Cerebras is partnering with CrowdStrike to accelerate that defense loop 👇
Thank you, @gdb, for highlighting how AI-enabled cybersecurity is more critical than ever!

OpenAI took 25% of its production engineers off every project and told them: you are just securing now. Their top model hunted in their infrastructure until it saturated (stopped finding new issues).
Will everyone else follow?
New physics of cybersecurity
@gdb / @NoPriorsPod
Your AI agent has a to-do list. Waiting shouldn’t be the longest item.
Cerebras’ Andy Hock joins theCUBE to discuss why inference speed matters for reasoning models and AI agents.
Where would less waiting make the biggest difference?
Watch the full conversation with Andy Hock and theCUBE:
youtube.com/watch?v=H2GnroPz…

AI agents rely on a good harness.
Faster inference gives a harness room to inspect results and recover sooner, while you steer the work. @MilksandMatcha breaks down the loop.

“If you’ve ever asked AI to do something and then drummed your fingers waiting for it to respond, you’ve run up against slow inference. To pick up the pace, Cerebras developed its own inference platform from the semiconductor wafer up.”
Cerebras is proud to be named in @FastCompany 's 2026 Next Big Things in Tech list.
