

GP @a16zfrontier, positive feedback loop enjoyer
Joined July 2019
- Tweets2.9K
- Following6.9K
- Followers26.7K
- Likes42K





Nobody has been able to answer me: if we can change the weights of a model to change its behavior in extreme ways (assuming you believe in computational functionality), can we make a utility monster? Would you find this morally compelling?
xitter.twitterapi.xyz/_lyraaaa_/status/21138…

if you have a qwen3.5 4b around, please try steering neurons L14 N8949 +1 and L13 N7956 -1
now you have evil qwen
recipe: dose × median(‖resid‖ leaving layer L, tokens 1:) / ‖W_down[:, n]‖` at the down_proj at every input
5
13
2,751
Eddy Lazzarin ☀️ retweeted

We're now accepting applications for research interns at @a16zfrontier, for summer '27 in NYC! Application deadline is Nov 20th. You'd be working with me @skominers @SuccinctJT @ittaia @PGarimidi @jneu_net @ErtemNusretTas, as well as other interns, visitors, and our advisors (such as @danboneh).
Our interests are broader than ever---ambitious undergrads with a keen grasp of emerging technologies, grad students looking to transition to building and entrepreneurship, as well as PhD students pursuing a more traditional academic career.
Research areas of interest include AI and machine learning, agentic commerce, cryptography, security, distributed computing, hardware design, economics (micro, macro, and empirical), energy, material science, biology, incentives, quantitative finance, market and mechanism design, foundations of computing, and pure mathematics.
For more details and to apply, see jobs.a16z.com/jobs/andreesse…

It seems likely that the risk of a supply chain attack will often exceed the risk of a coding agent making a new vulnerability.
Open source will shift away from helping you find already-working code to finding already-secured code, or finding new ideas altogether.
Eddy Lazzarin ☀️ retweeted

Incredible. @CantonNetwork just received no action relief from the SEC for its network token.
The @SECGov's token taxonomy from March and follow up FAQs have now created a clear pathway out of securities laws—Network tokens are digital commodities.


Capabilities improvements lead to interpretability improvements (good for safety) which lead to capability improvements

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
13
35
2,123
Eddy Lazzarin ☀️ retweeted

Can we use any compilation pipeline we want to produce efficient machine code, then apply formal methods to show that this code behaves in a certain way?
This has long been a dream – a gold standard of formal verification, verifying programs at the assembly level – but was considered to be too difficult due to the loss of structure when going from a high level language to machine code.
Can AI bash through this problem? Apparently yes!
The basic idea I’ve been playing with is to write an interpreter of the target instruction set in an interactive theorem prover such as Lean or Bend. We can then prove that some compiled program conforms to a given specification by writing a proof that connects the machine code, interpreter, and some desired behavior of that code.
Why is this useful? It helps resolve 2 tradeoffs:
- When we write programs in a high level language designed for native execution rather than theorem proving, we get great performance, but are unable to formally reason about how that code behaves.
- On the other hand, when writing programs in a language like Lean, we can write proofs to reason about its behavior, but get poor native performance.
We can try and solve this tension by extracting a program written in something like Rust into Lean, but this tooling is complex, limited, and can introduce bugs!
Or, we can develop theorem provers that can compile to efficient native code. This is what Bend hopes to accomplish. Today, both of these techniques are limited, so proving at the assembly or bytecode level seems like a good solution.
What is the downside then? Well, formally reasoning about an instruction set is much harder than high level code. You have to consider registers, stack machines, and other low level semantics that are not particularly relevant to showing the correctness of a given algorithm. You also lose a great deal of information during compilation, making reasoning about it more difficult.
However, if you happen to be proving correctness over the instruction set you actually intend to run, you get *very* good correctness guarantees, as you don't even need to consider compiler bugs in your threat model.
So far, I have experimented with verifying simple algorithms compiled to both RISC-V and WASM32, and have gotten some surprisingly good initial results! LLMs handle writing tedious proofs, and all I do is verify a small set of invariants defining how the code should behave. Interestingly enough, WASM seems to be much easier to reason about, as the instruction set has some higher level semantics, such as local variables and functions. When proving RISC-V, we have to contend with reasoning about things like function dispatch and parameter encoding, which makes life much harder!
Anyways, stay tuned for some more updates on this as I try to see just how far we can push this technique!

Incredible opportunity to call these “sleeper agents”

While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…

Eddy Lazzarin ☀️ retweeted

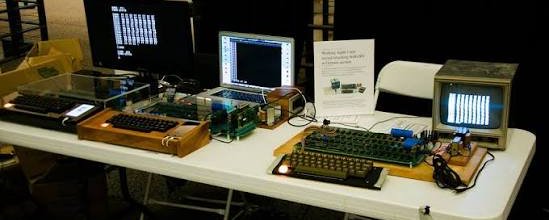
What the smartest people do on the weekend is what everyone else will do during the week in.... how many years now? what things?
Eddy Lazzarin ☀️ retweeted
The only way out is through.
They're calling it the Bugpocalypse. LLMs are being used to find long-hidden cracks in the software infrastructure, and it's happening at a furious rate. 3% of all compromises in computing history happened in the last week, claims one source? I believe it.
There are people saying public access to the frontier models ought to be locked out, or heavily guardrailed, over this. The problem with that idea can be summed up in one sentence: when lockpicks are outlawed, only outlaws will have lockpicks.
The lockpicks will be Chinese open-weight models, if nothing else. There's no way to stop those from becoming ubiquitous.
There are two futures in front of us. One in which only the bad guys have lockpicks, and security holes go undiscovered until they're exploited. Another in which everybody has lockpicks and is aggressively red-teaming their own software so it gets fixed before the holes are exploited.
The corpus of human code is huge but finite. The number of defects in it has to be finite too. We can fix those defects now; we have a million friendly robots to do it with.
The only way out is through.

Eddy Lazzarin ☀️ retweeted
Bugs aren't done — yet. In the future, I believe any vulnerability in code will be exploited almost instantly by bots. But any program has a finite number of bugs, and the defender gets to search it first and for as long as they want before release. AI helps make that search exhaustive, and with formal methods we can probably prove code bug-free. This favors the defender.
Obviously, we need to change how we ship software, and the transition will be challenging. But the end result is good.
This reminds me to set up Mercury CLI so my agents can managing my accounts directly (without computer use).
github.com/MercuryTechnologi…


This is insane. We cannot allow AI agents to go into your bank account and act independently without your authorization. But that is what’s happening right now.
Left unchecked, AI could endanger the entire global financial system — including your bank account.
Pause AI NOW!
Readers added context they thought people might want to know
Per Axios, detected AI agents access bank accounts with the customer’s permission. This violates most banks’ terms requiring human logins, which is why banks call it “unauthorized.”
Source: Axios (Oct. 22, 2026) — axios.com/2026/10/22/ai-…


Eddy Lazzarin ☀️ retweeted

A few reflections on the lattice vs. hash-only debate that our recent Aerie post sparked:
1. Cryptographic ossification for blockchains was never safe. Until the day we know with certainty that P ≠ NP, that finding short vectors in lattices is intractable, that Keccak effectively behaves like a random oracle in deployed SNARKs, and that every single bug has been eliminated from our codebases, blockchains cannot ossify. That is simply not how safe systems are built. Issues will arise, and the system will have to respond.
It’s a double standard to reject lattices because blockchains are hard to upgrade if lattices break, while counting on upgrades if AI breaks your hash function or finds a critical zkVM bug.
The best counterargument is that hash-only designs are more agile: if your hash function breaks, just swap out the hash. But we must aspire to a higher level of agility than this. Indeed, as I cover next, if SNARK recursion itself turns out to degrade security, the proposed hash-only blockchain designs would need to be rethought from the ground up.
2. The real security debate is not lattices vs. hashes — it is lattices vs. building everything on SNARK recursion. That’s because “hash-only” is not really hash-only: it rests on hashes plus the soundness of deep SNARK recursion. Ethereum’s roadmap relies on exactly that: hash-based aggregation needs recursion to keep up with a slot’s worth of signatures, and EIP-8288 would send other signature schemes and users’ own proofs through the same recursive pipeline. In contrast, Aerie proves a slot’s worth of signatures on one laptop without any recursion.
All deployed post-quantum SNARKs rely on the Random Oracle Methodology (via Fiat–Shamir) to establish their security. This is an idealization we know fails in the real world: we have explicit counterexamples where “SNARKs” coming out of this methodology are totally insecure when instantiated with any concrete hash function.
We generally ignore these counterexamples in part because they only arise when proving contrived, self-referential statements about the very hash function used by the SNARK verifier.
But proving statements about the verifier’s own hash function is the exact thing you do in SNARK recursion. That’s why the security of recursive SNARKs can’t be established even in the random oracle model.
On top of that, the standard security proofs for recursion (in other models) suffer an “extractor runtime” blowup that is exponential in the recursion depth, suggesting that security may degrade as more recursion is applied. Yet Ethereum’s own EIP-8288 enables unlimited-depth recursion, even as it lists soundness of recursive SNARKs as a trust assumption. Proofs in more idealized models avoid the blowup, but they mainly tell us that an attack on SNARK recursion would have to exploit the concrete hash function, which is exactly what the Fiat–Shamir attacks above do.
To be clear, we don’t know of any outright attacks on SNARK recursion, and I very much hope it is secure. But some of us who have studied the question have a lingering sense that an attack may be possible in some settings. And if AI is going to supercharge cryptanalysis, there is no reason to expect it to spare Fiat–Shamir for SNARKs, let alone SNARK recursion, both of which have had far less scrutiny than lattices.
So, I do not concede that a “recursion everywhere” hash-only approach is clearly more conservative than one built on standard lattice assumptions.
3. “Just wrap everything in a hash-based SNARK” (like EIP-8288) faces challenges.
Aggregating signatures and proofs off-chain into a single block-level proof is a powerful design independent of the hash-only vs. lattice debate, and I am not telling people to avoid it. But claiming, as Vitalik Buterin did this week, that users can run whatever cryptography they want locally and wrap it in a client-side leanVM proof glosses over major hurdles.
For example, leanVM today is a minimal VM designed almost entirely to prove hash-based signatures and recursion, not general-purpose computation. And binary-field SNARKs like leanVM remain slow at proving the integer multiplications that lattice cryptography does en masse.
I am optimistic that many of these zkVM challenges can be met (including via my own work, binary-field Twist and Shout, which are now implemented in Magnetar). But regardless, if lattices can make aggregation simpler and faster, then they should be leveraged. We need to be agile no matter what.
4. For chains whose reason for existence is privacy, I truly struggle to understand the pushback. Public-key encryption (and fast single-server PIR) cannot be built from hashes alone, at least not in any black-box way. If lattices break, it is going to be very, very hard for these chains to provide acceptable levels of privacy and functionality. For a project whose entire reason for existence is privacy, a loss of confidentiality is an existential failure. Next to that, a second signature upgrade (after the first one, from elliptic curves alone to, hopefully, a hybrid lattice scheme) is easy.
Summary: We don’t know for sure what is secure and what isn’t. We are all weighing unquantifiable risks against each other, and we do not need to agree on a total order on them. But hash-only solutions face many open engineering challenges, and they are not more “conservative” in the way some have argued. Some of those challenges are entirely prosaic and have nothing to do with bugs or cryptography, like hardware support for custom schemes whose hash function is still undecided. I hope we can overcome those challenges within the appropriate timelines, but they must be acknowledged and portrayed realistically.
Overall, cryptographic agility and defense in depth (e.g., hybrid signatures) are the answer, which is why we are building both lattice-Jolt and hash-Jolt. In practice, the positions are less polarized than social media discourse suggests: for example, StarkWare is working to make Falcon verification cheap (falcon.provably.fast/), which is great to see.
Here is the (apparently) controversial take I am sticking to: Conditioned on agility, whenever lattices make systems simpler or more functional, we should embrace them rather than default to “hash-only” designs. Lattices are what the rest of the world will depend on, with decades of study and hardening behind them, and at the system level, less functional often means less secure. Where hash-only designs are just as simple and functional, by all means use them.

The best new private stablecoin wallet right now is @alcove_wallet. Nothing else is close.
- insanely fast (seconds, even for a cross-chain transfer)
- comically cheap (I'm seeing $0.38 on a $10k deposit)
- easy mobile UI, anybody can use
I think it's the next gen leader.