

san francisco
Joined December 2015
- Tweets2.3K
- Following880
- Followers3.4K
- Likes14.5K




congrats to @WellspinDesign on their official launch today! super proud to have been one of their earliest design partners :)

Meet the new Wellspin.
We partner with founders to spin up brands, websites and products, from the first impression to the everyday experience.
Let’s build yours: wellspin.design
excited to partner with @youdotcom to serve kimi k3.1 pro on inference router from day 0!
moonshot ai's latest open-weight model is now available with a 99.9% uptime SLA from the you.com team and zero data retention.
try it today (link in thread)


Kimi K3.1 Pro is live on Inference Router from day 0.
K3.1 is @Kimi_Moonshot's most capable open-weight model yet, with a 1M context window and a reported 65.7% on Terminal-Bench 4.0.
Run it in production with at least 99.9% uptime SLA, US hosting and ZDR available. No upfront commitment.


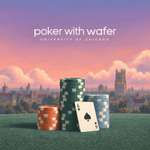
join the @wafer_ai team for poker, food, and drinks at the University of Chicago!
we’d love to meet people doing exceptional things and hear what you’re working on.
October 28 · 5–9pm CDT · UChicago
request to join below


we’re partnering with @youdotcom to bring Wafer’s inference to developers through its new Inference Router!
access @wafer_ai through one OpenAI-compatible API, with multi-provider failover and built-in web search from You.com.
link in thread 🧵
Introducing Inference Router: enterprise-grade inference on demand.
Kimi K3, GLM 5.3, DeepSeek V4.1 Flash, Qwen3.8 Flash, Muse Spark 1.3, Mercury 3 and more, available with an uptime SLA of at least 99.9%. US hosting and web search built in.
you.com/router


@wafer_ai's gpu performance engineering guide is getting some big updates!
what resources are still missing?
we're doing a massive update on Wafer's popular open source guide to GPU performance engineering!
a few cool resources going into this update:
⠀
1. Stream-K: why a matmul can leave part of the GPU idle while the last blocks finish, and how dividing the multiply-accumulate work more evenly helps.
⠀
2. tcgen05 for dummies: gau-nernst builds a Blackwell matmul step by step. Tensor Memory, asynchronous copies and pipelining, with code you can follow as the kernel develops.
⠀
3. Thinking Machines' Defeating Nondeterminism: how changing the batch can change the order of floating-point additions, and why that can change inference results. then, how to make the kernels batch-invariant.
⠀
4. Triton's Linear Layouts: how tensor elements are arranged across threads and registers, and the data movement needed to change that arrangement.
⠀
the update also expands the quantization, speculative decoding and hardware references.
⠀
the guide starts with one inference request, then moves through GPU fundamentals, kernels, serving engines and distributed systems. start at the beginning if you're new; use the individual sections when you hit a specific problem.
⠀
if you know a primary source that explains one of these topics better, open a PR.

you'll know more about blackwell tuning than 93.73% of people if you fully understand the Blackwell Tuning Guide
it covers register limits, thread-block clusters, distributed shared memory, shared-memory carveouts, L2 persistence, and NVLink peer access.
follow and save to keep up with the series. links in thread 🧵
we launched the most comprehensive ai performance engineering repo in the world
we're posting every single resource
follow and save to keep up with the series. links in thread 🧵
part 14: Blackwell Tuning Guide
NVIDIA covers the execution limits, memory hierarchy, and communication mechanisms behind tuning AI workloads on Blackwell:
- register budgets, resident warps, and occupancy in fused AI kernels.
- shared-memory limits for attention and matmul tiles across Blackwell compute capabilities.
- thread-block clusters and distributed shared memory for exchanging tensor data across blocks.
- 8-block portable clusters, B200's optional 16-block clusters, and the parallelism tradeoff of larger clusters.
- L1/shared-memory carveouts and the balance between caching and explicit tensor staging.
- L2 cache persistence for inference kernels that reuse the same tensors.
- NVLink peer access and direct tensor transfers between GPUs in model-parallel inference.
the guide connects Blackwell's hardware limits to kernel design decisions like tile size, block cooperation, and tensor reuse, helping engineers choose what to test when tuning attention, matmul, and multi-GPU inference.

you'll know more about gpu execution and memory management than 93.51% of people if you fully understand the Programming Model chapter of NVIDIA's CUDA Programming Guide
it covers thread blocks, warps, branch divergence, SIMT and tile programming, shared memory, block clusters, and data placement across cpus and gpus.
follow and save to keep up with the series. links in thread 🧵

we launched the most comprehensive ai performance engineering repo in the world
now we're posting every single resource
follow and save to keep up with the series. links in thread 🧵
part 11: CUDA Programming Model
optimizing matrix multiplication and reductions in training or inference means deciding how to divide tensor work, which threads exchange values, and where the data will live. NVIDIA's Programming Model chapter explains the CUDA rules that constrain those choices.
NVIDIA explains the execution and memory rules behind these AI performance engineering decisions:
- partitioning matmuls and reductions. each thread block executes on one streaming multiprocessor (SM), and ordinary blocks have no guaranteed scheduling order. engineers must divide tensor work without assuming a particular block will run first.
- diagnosing unused execution lanes. warps contain 32 threads. divergent branches mask lanes, while block sizes that are not multiples of 32 leave the final warp partly empty. check block sizes and branch patterns when a tensor kernel leaves lanes unused.
- choosing a programming model per kernel. SIMT (single instruction, multiple threads) gives per-thread control; tile programming lets the compiler map matmuls and reductions to threads within a block. tile indexing and boundary handling matter when tensor dimensions leave partial edge tiles.
- sizing on-chip intermediate data. registers hold per-thread state, while shared memory lets a block's threads exchange values. their allocation limits constrain block size and how many blocks can reside on an SM, a tradeoff when keeping more tensor data on chip.
- coordinating work across blocks. on GPUs with compute capability 9.0 or higher, blocks in the same cluster can synchronize and access one another's shared memory. engineers can evaluate this for operators that share intermediate results across several blocks.
- evaluating data movement between CPU and GPU. unified memory lets both processors access the same allocation, but placement and migration affect cost. for CPU preprocessing followed by GPU execution, check data residency, transfers, and remote accesses.
- testing compute and memory placement. on GPUs with multiple locality domains, engineers can partition both tensor work and data, run the partitions in parallel, and place each partition's computation near its memory. performance gains depend on the workload.
use these mechanisms to choose the next kernel experiment: change the work partition, adjust intermediate storage, or move data closer to the computation, then measure the result.

excited to announce that @wafer_ai is live on @concentrateai, the ai gateway for fast-growing ai companies!
our agents continuously optimize inference, with speedups as high as 11.3x.
try wafer endpoints on concentrate
link in thread 🧵

if i had to make a wild uninformed and unbiased guess it’s probably latch bio

I’ve had 3 diff people tell me they are 100% sure this “fastest to $1B annualized revenue” is 3 diff companies.
Very likely more than 1 data co has recently hit that mark, many of which are on Pavlov’s List.
Many more will get there in the next 6mos.
Total data spend is >$15B.

12
1,446
you'll know more about CUDA kernels, GPU memory management, asynchronous execution, and multi-GPU synchronization than 99.41% of people if you fully understand the CUDA Programming Guide
it covers GPU execution, CUDA Tile, memory coalescing, TMA pipelines, CUDA Graphs, KV cache memory management, multi-GPU synchronization, and floating-point numerics.
this is only the tenth resource in the ai performance engineering repo btw.
follow and save to keep up with the series. links in thread 🧵

we launched the most comprehensive ai performance engineering repo in the world
and we're posting every single resource
follow and save to keep up with the series. links in thread 🧵
part 10: CUDA Programming Guide
making an LLM faster means understanding where execution is waiting. an attention kernel can wait for its next tile of data, while the serving runtime can leave the GPU waiting for the next launch.
NVIDIA's CUDA Programming Guide explains the mechanisms behind those waits. for a modern AI performance engineer working in PyTorch, Triton, or CUDA, it helps with:
- tuning attention, matmul, and normalization kernels. the SIMT and CUDA Tile chapters connect layouts and data reuse to GPU execution. the resource guidance explains why larger tiles or more fusion can introduce register spills.
- overlapping data movement with computation. asynchronous copies, TMA, and producer/consumer pipelines explain how supported GPUs can load the next tile while processing the current one, with the synchronization required to reuse buffers safely.
- managing growing KV caches. the virtual memory chapter explicitly connects its allocation model to LLM serving: reserve an address range, then map additional physical memory into it as the cache grows, without relocating existing data.
- reducing overhead between inference kernels. CUDA Graphs reduce repeated CPU launch setup, while stream-ordered allocation avoids broad synchronization around temporary memory. these matter when launch and allocation costs contribute to request latency.
- diagnosing stalls across GPUs. the guide explains peer access and communication dependencies, including how a compute kernel's completion fence can wait on unrelated NCCL writes. memory synchronization domains can reduce that interference on supported hardware.
- evaluating CPU memory offload. the memory chapters explain how residency, migration, and interconnect traffic affect access cost. that helps assess the latency and capacity tradeoffs of keeping model data in CPU memory on supported systems.
- validating an optimization before deploying it. the appendices explain how reduction order, accumulation precision, and fast math can change results, and which hardware capabilities and resource limits a kernel depends on.
when a training step or inference request slows down, these details help narrow the next experiment: change the kernel, move less data, adjust allocation, or remove an unnecessary wait.

excited to host sf tech weeks afters! dm for invite
keep SF Tech Week going at Wafer After Hours 🎮
this month it's a Smash Bros tournament
one champion. unlimited bragging rights. 🏆
poker and more to play, then drinks at House of Shields
sat oct 10, 7-11pm in San Francisco. request an invite:
luma.com/z54figtk

17
799
you'll know more about GPU programming and AI performance than 99.32% of people if you fully understand this lecture series
it covers profiling, CUDA and Triton kernels, FlashAttention, FP8 and FP4 numerics, distributed training, and inference serving with SGLang and vLLM.
this is only the ninth resource in the ai performance engineering repo btw.
save and follow to keep up with the series
we launched the most comprehensive ai performance engineering repo in the world
follow and save to keep up with the series. links in thread 🧵
part 9: GPU Mode lectures 🐐
this one entry is a full resource repo of its own. GPU MODE collects lectures, slides, notebooks, and code covering GPU programming and the systems behind modern AI training and inference.
the lectures help AI performance engineers diagnose slow training and inference and decide what to optimize. the examples show how kernel memory access, numerical precision, GPU communication, and runtime scheduling affect model performance.
GPU MODE's speakers connect those problems to implementation details:
- profiling with PyTorch and Nsight, tracing operations to GPU kernels and memory transfers, with timing examples that account for warmup and synchronization.
- GPU memory and execution, using coalescing, shared-memory tiling, and occupancy to explain how thread mapping and data reuse affect performance.
- kernel development with Triton, CuTe, and Gluon, including tensor layouts that map data to threads and memory, and control over asynchronous GPU operations.
- attention kernels, working through FlashAttention's tiling and FlashAttention-3's overlap of data movement, matrix multiplication, and softmax on Hopper.
- kernel fusion, inspecting code from torch.compile and writing custom kernels that reduce intermediate memory traffic, with examples that compare memory use and execution time.
- low-precision computation, covering FP8 and FP4 formats, quantized optimizer states, and the rounding and scaling choices that affect numerical error.
- distributed training, following PyTorch gradient synchronization into NCCL AllReduce and examining the communication required to combine results across GPUs.
- inference serving, studying SGLang's CPU/GPU scheduling overlap and vLLM speculative decoding examples that weigh accepted tokens against drafting and verification costs.
use the collection to build a study plan or investigate a bottleneck in a real workload. work through the relevant implementation, check its assumptions and numerical results, and measure the tradeoff on the hardware and input shapes that matter for the application.

GPU MODE Lectures
By the GPU MODE community and contributing speakers
github.com/gpu-mode/lectures

2
288
taps at wafer slides from 6 months ago


you'll know more about how to benchmark LLM inference, compare serving configurations, and plan capacity around latency targets than 99.152% of people if you fully understand this paper
this is only the eighth resource in the ai performance engineering repo btw
follow and save to keep up with the series
this is a must-read if you want to be a top 1% ai performance engineers
follow and save to keep up with the series. links in thread 🧵
part 8: Etalon: Holistic Performance Evaluation Framework for LLM Inference Systems
Amey Agrawal and coauthors explain how serving decisions shape the timing of streamed LLM responses. for AI performance engineers evaluating batching, chunked prefill, or speculative decoding, the paper provides a framework for assessing token delivery against application-specific timing targets.
the authors connect scheduling behavior, token arrival traces, and service targets:
- prefill and decode interference: a long prefill can delay ongoing decode work. chunked prefill divides that prompt processing across batches, so the amount of prefill work per batch can affect both first-token latency and interruptions to existing streams.
- first-token latency: time to first token (TTFT) includes scheduling delay and prompt processing. the authors propose profiling isolated requests across prompt lengths and adding a scheduling allowance to set first-token deadlines.
- averages and latency distributions: time per output token (TPOT) can hide generation pauses, while percentiles of time between tokens (TBT) omit where those pauses occurred within a response. per-request token arrival traces preserve the order and gaps observed by the client.
- speculative decoding and buffering: several tokens can arrive in one burst. a client can buffer them for steady display, letting work completed ahead of the consumption rate cover some later gaps.
- deadline-based evaluation: fluidity-index measures the fraction of deadlines met within a request. tokens arriving before their deadlines build slack. if a token misses its deadline, Etalon counts missed deadline slots and resets subsequent deadlines from that token's arrival.
- fluid token generation rate: the highest playback rate inferred from the evaluated requests that meets a chosen fluidity target for a specified share of requests. this supports API comparisons under a defined fluidity requirement.
- capacity planning: Etalon estimates the maximum request rate a replica can sustain under specified targets on the tested workload. this informs estimates of how many replicas a deployment needs.
for a controlled deployment comparison, keep the model, hardware, workload, and service targets fixed, then use capacity search to compare serving configurations. engineers choose the settings to evaluate.

Etalon: Holistic Performance Evaluation Framework for LLM Inference Systems by Amey Agrawal et al.: arxiv.org/html/2407.07000
2
201
you'll know more about batching, weight sharding, and KV cache traffic than 99.92% of people if you fully understand this paper
follow and save to keep up with wafer ai performance engineering series
we gathered all the resources you'll ever need to become the most cracked ai performance engineer
follow and save to keep up with the series. links in thread 🧵
part 7: Efficiently Scaling Transformer Inference
Reiner Pope and coauthors studied PaLM inference on TPU v4. the paper gives performance engineers a way to reason about where weights, activations, and KV caches should live, what must move each step, and which transfers limit latency.
the paper's mechanisms suggest these checks for an inference deployment:
- prefill and decode can have different arithmetic intensity, meaning computation per byte transferred. prefill can process many prompt tokens in one pass; standard autoregressive decode produces one new token per sequence per step. larger decode batches amortize weight reads, but add sequence-specific KV cache traffic. sweep batch size with context length and profile the linear layers and attention to locate the bandwidth or compute limit.
- tensor parallelism can reduce local compute without removing the communication bottleneck. in the paper's 1D layout, activation-aggregation time stays roughly constant as chip count grows for a fixed workload. 2D partitioning splits both weight dimensions so each chip communicates smaller activation shards. evaluate this against the actual interconnect and matrix dimensions before increasing the parallelism degree.
- the best tensor to move changes with the token batch. weight-stationary layouts exchange activations; weight-gathered layouts transfer more weights to reduce activation exchange. large prefills can justify that trade because their activation tensors are large. count the tokens processed per forward pass, including prompt tokens during prefill, when comparing those layouts.
- multiquery attention shares one KV head across query heads, but a head-sharded layout can replicate that cache across devices. the paper shards attention across the batch during decode and exchanges current-step activations to reduce cache reads per chip. in vLLM's grouped-query attention deployments, check whether tensor parallelism exceeds the KV-head count and introduces cache replication before estimating per-GPU capacity.
- KV cache capacity and prefill attention intermediates are separate memory problems. at a fixed batch size and query-head count, sharing KV heads does not shrink the full attention-score tensor. for dense prefill, that tensor's element count grows with the square of sequence length. Appendix G discusses microbatching to reduce temporary allocations and FlashAttention to avoid materializing the full score matrix. use that distinction to identify whether a memory failure comes from retained KV state or temporary attention allocations.
- communication overlap depends on the execution schedule and tensor layout. the authors use Looped CollectiveEinsum to overlap collectives with matrix multiplication, including choosing output sharding that exposes overlap opportunities. inspect a GPU timeline for exposed communication and dependent compute stalls; an asynchronous collective does not establish that its cost is hidden.
- quantization changes different bottlenecks depending on what is quantized. the paper stores weights in int8 while retaining bfloat16 matrix arithmetic. this reduces weight-loading traffic, but does not provide faster arithmetic for compute-bound batches. evaluate weight, activation, and KV cache precision against the measured bottleneck and benchmark the effect on both phases.
- benchmark the operating point that the application needs. the paper compares latency with accelerator-time per token and model FLOPS utilization. in a serving system, track time to first token, inter-token latency, and throughput under the target load. keep queueing time separate from prefill time.
the practical use is to narrow an optimization experiment: estimate compute, HBM traffic, and collective costs for the actual workload, inspect the bottleneck, change the relevant layout or precision, and remeasure at the same latency target.

Efficiently Scaling Transformer Inference — Reiner Pope, Sholto Douglas, Aakanksha Chowdhery, Jacob Devlin, James Bradbury, Anselm Levskaya, Jonathan Heek, Kefan Xiao, Shivani Agrawal, Jeff Dean
proceedings.mlsys.org/paper_…

