

Hi, this is https://xitter.twitterapi.xyz/t.co/EO7MXLjjSU official account. We build systems for efficient LLM serving, including KTransformers, Mooncake and AgentENV.
Beijing
Joined August 2018
- Tweets102
- Following110
- Followers1.2K
- Likes138




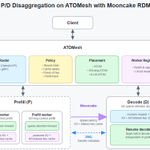
🚀 ATOM Meets Mooncake: Scaling Agentic LLM Serving on AMD Instinct GPUs!
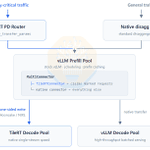
A deep dive into how NeuroSpark AI deploys AMD's ATOM and Mooncake to serve GLM-5.3 across 32 AMD Instinct MI350X GPUs.
With ATOM, ATOMesh and Mooncake's shared KV pool:
🔥 95–96% KV cache reuse on production traffic
⚡ Up to 2× throughput vs. per-server KV pools in AgentX benchmarks
🚀 Scalable agentic LLM serving across servers
Read the full story 👇
kvcache.ai/blog/atom-meets-m…

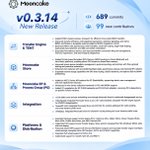
🚀 Mooncake v0.3.14 is officially released!
This release brings major upgrades across Mooncake Store, Transfer Engine, TENT, Expert Parallelism (EP), Process Group (PG), ecosystem integrations, and hardware support.
With 689 commits and 99 new contributors, a huge thank you to everyone in the Mooncake community! ❤️
🌟 Highlights:
- Transfer Engine Upgrades: Shared-memory transport, RDMA optimizations, and enhanced TENT multi-rail capabilities.
- GPU Memory Pooling: New NVLink-based Extended GPU Memory (EGM) support.
- EP & PG Enhancements: Elastic communication, device-side collectives, and JIT compilation.
- Ecosystem & Hardware Expansion: Deeper integrations and broader support for AI accelerator platforms.
🤖 Made with AI

Exciting to see Mooncake Store highlighted by @SemiAnalysis_ in the latest Rubin NVL72 AgentX results!
Mooncake Store recently added support for Extended GPU Memory (EGM), enabling KV cache pooling across all 18 Rubin compute trays via NVLink and delivering over 10x higher bandwidth compared to the previous RDMA-based approach.
Full GLM-5.3 benchmark results and configurations from InferenceX:
inferencex.semianalysis.com/…


This Rubin submission uses the new @KVCache_AI Mooncake Store feature of Extended GPU Memory, where KVCache stored on Vera's LPDDR5X is pooled across all 18 Rubin compute trays using NVLink instead of the previous method of using RDMA, resulting in greater than 10x better bandwidth. (2/2)
🚀 Exciting news! Mooncake is now listed in the CNCF Landscape!
We're excited to be part of the cloud native ecosystem, bringing high-performance KV cache management and data transfer to LLM inference at scale.

Elastic Expert Parallelism scaling in SGLang!
Excited to see Mooncake PG powering elastic membership and synchronization, working alongside @sgl_project and NIXL to enable more elastic and efficient MoE inference without restarting live deployments!
🔗 lmsys.org/blog/2026-10-21-el…

Great to see Mooncake powering KV cache offloading in @PrimeIntellect's Prime Inference stack! 🚀
This blog dives into building fast, reliable inference for long-context agent workloads, featuring Dynamo, vLLM, Mooncake and FlashInfer.
Read more:
🔗 primeintellect.ai/blog/prime…

🚀 Excited to share our new paper, KTransformers-FineTune (KT-FT), developed in collaboration with the amazing @llamafactory_ai team!
Fine-tune 671B MoE models with just 16GB GPU VRAM + CPU memory.
⚡ 2.5–21.2× faster than offloading baselines
🧠 Up to 128K-token contexts
🔧 CPU-GPU co-computation, beyond offloading
📄 Paper: github.com/kvcache-ai/ktrans…

Looking forward to learning how Mooncake + HiCache are pushing KV cache efficiency further in real-world deployments. 🚀

Excited to be speaking at the first SGLang Summit (@sgl_project), Nov 12–13 at Fort Mason in SF!
My team (@areneau @KastanDay ) and I are looking forward to presenting our work on system one models (Clef and Clairic), and sharing how we are maximizing KV cache hit rates using a multi-deployment Mooncake cluster with HiCache. Come say hi if you're there!

4
235
Today is the Mid-Autumn Festival, the day when the moon is said to shine at its fullest and brightest.
Mooncakes, rich pastries filled with sweet bean or lotus seed paste, are shared and enjoyed with family and friends during this festival.
As the poem goes: “The bright moon rises over the sea; though far apart, we share this moment together.”
Wishing everyone a happy Mid-Autumn Festival and a joyful time with your family! 🥮
🤖 Made with AI
Huge congrats to the @vllm_project team on pushing DSpark training for Kimi-K3 to this scale! 🚀
As the high-performance data plane behind the disaggregated pipeline, Mooncake moves hidden states between vLLM inference and training workers, fully utilizing RDMA bandwidth with topology-aware routing and multi-NIC aggregation.
A great example of Mooncake powering large-scale AI data movement beyond KV cache transfer.
Read more: vllm.ai/blog/2026-09-15-kimi…


Kimi K3 is a 2.8T-parameter model. We trained a DSpark speculator for it, and the speedup holds up.
Single-stream math reasoning goes from ~110 to ~435 tokens/sec per user. Under concurrent load, up to ~3.5x higher output throughput at matched interactivity. The drafter is a 5B model proposing 8 tokens a step, and on math it gets ~6.4 of them accepted per round.
Training a drafter for a model this big meant going multi-node: Speculators plus a new Mooncake connector streaming hidden states between vLLM inference and training over RDMA. Two GB300 nodes to serve the target, one to train.
vllm.ai/blog/2026-09-15-kimi…
KVCache.AI retweeted

Full session, vLLM Office Hours #55: Mooncake + vLLM/llm-d deep dive: youtube.com/watch?v=RFyeBEy1…
Live every other Thursday: red.ht/office-hours

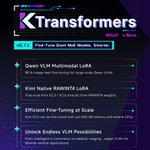
KTransformers v0.7.1 is here 🚀
Now supporting:
• Qwen VLM multimodal LoRA fine-tuning in BF16
• Native RAWINT4 LoRA for Kimi K2.5 / K2.6
Fine-tune massive VLM and MoE models with a more memory-efficient training path.

1
3
253
Docs & examples:
github.com/kvcache-ai/ktrans…
github.com/kvcache-ai/ktrans…

102
A great read on how GLM-5.3 helped optimize its own inference stack, tripling end-to-end throughput in under two weeks, all driven by a dense feedback loop between the agent and the system.
One particularly interesting case for us: while debugging a KV Transfer bottleneck, the team traced a >20% Prefill + KV Transfer performance gap due to Python GIL contention between DeepEP and the Mooncake Transfer thread. After releasing the GIL in the relevant C++ paths, the gap dropped to below 1%.

We’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
The system went from its first successful run to production readiness in less than two weeks, with end-to-end throughput tripling relative to the initial baseline.
The key was dense feedback: local correctness tests, execution traces, microbenchmarks, and end-to-end measurements that enabled targeted hypothesis testing rather than reliance on aggregate performance metrics alone.
z.ai/blog/glm-built-its-infe…

🚀 Over one trillion tokens per day, powered by Mooncake and SGLang.
@ApproachingAI shares the system architecture and engineering lessons behind its token factory, running leading trillion-parameter models with SGLang HiCache + Mooncake Store.
A deep dive into:
🏗️ Production architecture and system design trade-offs
⚡ Performance optimizations for trillion-token-scale workloads
🛡️ Failure isolation, fault tolerance, and recovery
Real production lessons on scaling KV cache reuse while meeting strict inference SLOs.
Read more: kvcache.ai/blog/mooncake-in-…

Thanks for the recognition!
Mooncake has always been focused on building high-performance storage and communication infrastructure for large-scale distributed LLM serving. We’re excited to keep pushing this forward with the community.

Gravity matters. I caught up with a friend today, and we talked about Mooncake @KVCache_AI — by 2026, whether for PD disaggregation or KV storage, Mooncake has become a first-class citizen and the default solution across the top 3 LLM inference engines.
Congratulations to the @lightseekorg TokenSpeed team! Great to see Kimi K3 optimizations running stably at production scale on GB300 and H200.

TokenSpeed × Kimi K3, Part I: TP8 optimization on GB300. Now stable 3+ weeks in production across ~1,000 B300 and ~2,000 H200 GPUs. Thanks @NVIDIAAI for engineering support and GB300 NVL72 access, and community teams for their support and contributions. 👇
lightseek.org/blog/kimi-k3-o…

1
478
The mystery model "Ox Alpha" is officially revealed as GLM-5.3-Flash, now with native KTransformers support!

Mooncake v0.3.13 is here! 🚀
This release brings major updates across Mooncake Store, Transfer Engine, Process Group, hardware support, and ecosystem integrations, with 276 commits and 33 new contributors. A huge thank you to all the users and contributors! ❤️
✨ Highlights:
• Mooncake Store: Multi-tenancy and NVMe KV SSD support
• Transfer Engine: Enhanced NVLink, IBGDA, and multi-rail transfer support
• Process Group: Dynamic membership and recovery
• New integrations with Miles and Speculators
• Broader platform support: NCCL, MUSA IPC, SUPA, and FlagCX
• Published wheel packages for ROCm

🚀 KTransformers v0.7.0 is here!
This release brings major upgrades for ultra-large MoE fine-tuning:
• Native FP8 Expert weights for LoRA, reducing host memory usage for DeepSeek-V3.1 from ~1.4 TB to ~800 GB
• Support AVX-512 backend for compatible AMD and x86 CPUs
• Support full fine-tuning
• Checkpoint saving and resuming
• A complete KTransformers × LLaMA-Factory fine-tuning Cookbook
🔗 Blog: kvcache.ai/blog/ktransformer…
#KTransformers #LLM #FineTuning #DeepSeek

